800 papers
Parameterized Approximation of Rectangle Stabbing
In the Rectangle Stabbing problem, input is a set ${\cal R}$ of axis-parallel rectangles and a set ${\cal L}$ of axis parallel lines in the plane. The task is to find a minimum size set ${\cal L}^* \subseteq {\cal L}$ such that for every rectangle $R \in {\cal R}$ there is a line $\ell \in {\cal L}^*$ such that $\ell$ intersects $R$. Gaur et al. [Journal of Algorithms, 2002] gave a polynomial time $2$-approximation algorithm, while Dom et al. [WALCOM 2009] and Giannopolous et al. [EuroCG 2009] independently showed that, assuming FPT $\neq$ W[1], there is no algorithm with running time $f(k)(|{\cal L}||{\cal R}|)^{O(1)}$ that determines whether there exists an optimal solution with at most $k$ lines. We give the first parameterized approximation algorithm for the problem with a ratio better than $2$. In particular we give an algorithm that given ${\cal R}$, ${\cal L}$, and an integer $k$ runs in time $k^{O(k)}(|{\cal L}||{\cal R}|)^{O(1)}$ and either correctly concludes that there does not exist a solution with at most $k$ lines, or produces a solution with at most $\frac{7k}{4}$ lines. We complement our algorithm by showing that unless FPT $=$ W[1], the Rectangle Stabbing problem does not admit a $(\frac{5}{4}-ε)$-approximation algorithm running in $f(k)(|{\cal L}||{\cal R}|)^{O(1)}$ time for any function $f$ and $ε> 0$.
2604.04282Apr 2026
View
Signotopes Induce Unique Sink Orientations on Grids
A unique sink orientation (USO) is an orientation of the edges of a polytope in which every face contains a unique sink. For a product of simplices $Δ_{m-1} \times Δ_{n-1}$, Felsner, Gärtner and Tschirschnitz (2005) characterize USOs which are induced by linear functions as the USOs on a $(m \times n)$-grid that correspond to a two-colored arrangement of lines. We generalize some of their results to products $Δ^1 \times\cdots\times Δ^r$ of $r$ simplices, USOs on $r$-dimensional grids and $(r+1)$-signotopes.
2604.04097Apr 2026
View 2604.04011
Separator for $c$-Packed Segments and Curves
We provide a simple algorithm for computing a balanced separator for a set of segments that is $c$-packed, showing that the separator cuts only $O(c)$ segments. While the result was known before, arguably our proof is simpler.
2604.04011Apr 2026
View2604.03889Surface Quadrilateral Meshing from Integrable Odeco Fields
We present a method for generating orthogonal quadrilateral meshes subject to user-defined feature alignment and sizing constraints. The approach relies on computing integrable orthogonal frame fields, whose symmetries are implicitly represented using orthogonally decomposable (odeco) tensors. We extend the existing 2D odeco integrability formulation to the 3D setting, and define the useful energies in a finite element approach. Our frame fields are shear-free (orthogonal) by construction, and we provide terms to minimize area and/or stretch distortion. The optimization naturally creates and places singularities to achieve integrability, obviating the need for user placement or greedy iterative methods. We validate the method on both smooth surfaces and feature-rich CAD models. Compared to previous works on integrable frame fields, we offer better performance in the presence of mesh sizing constraints and achieve lower distortion metrics.
2604.03889Apr 2026
View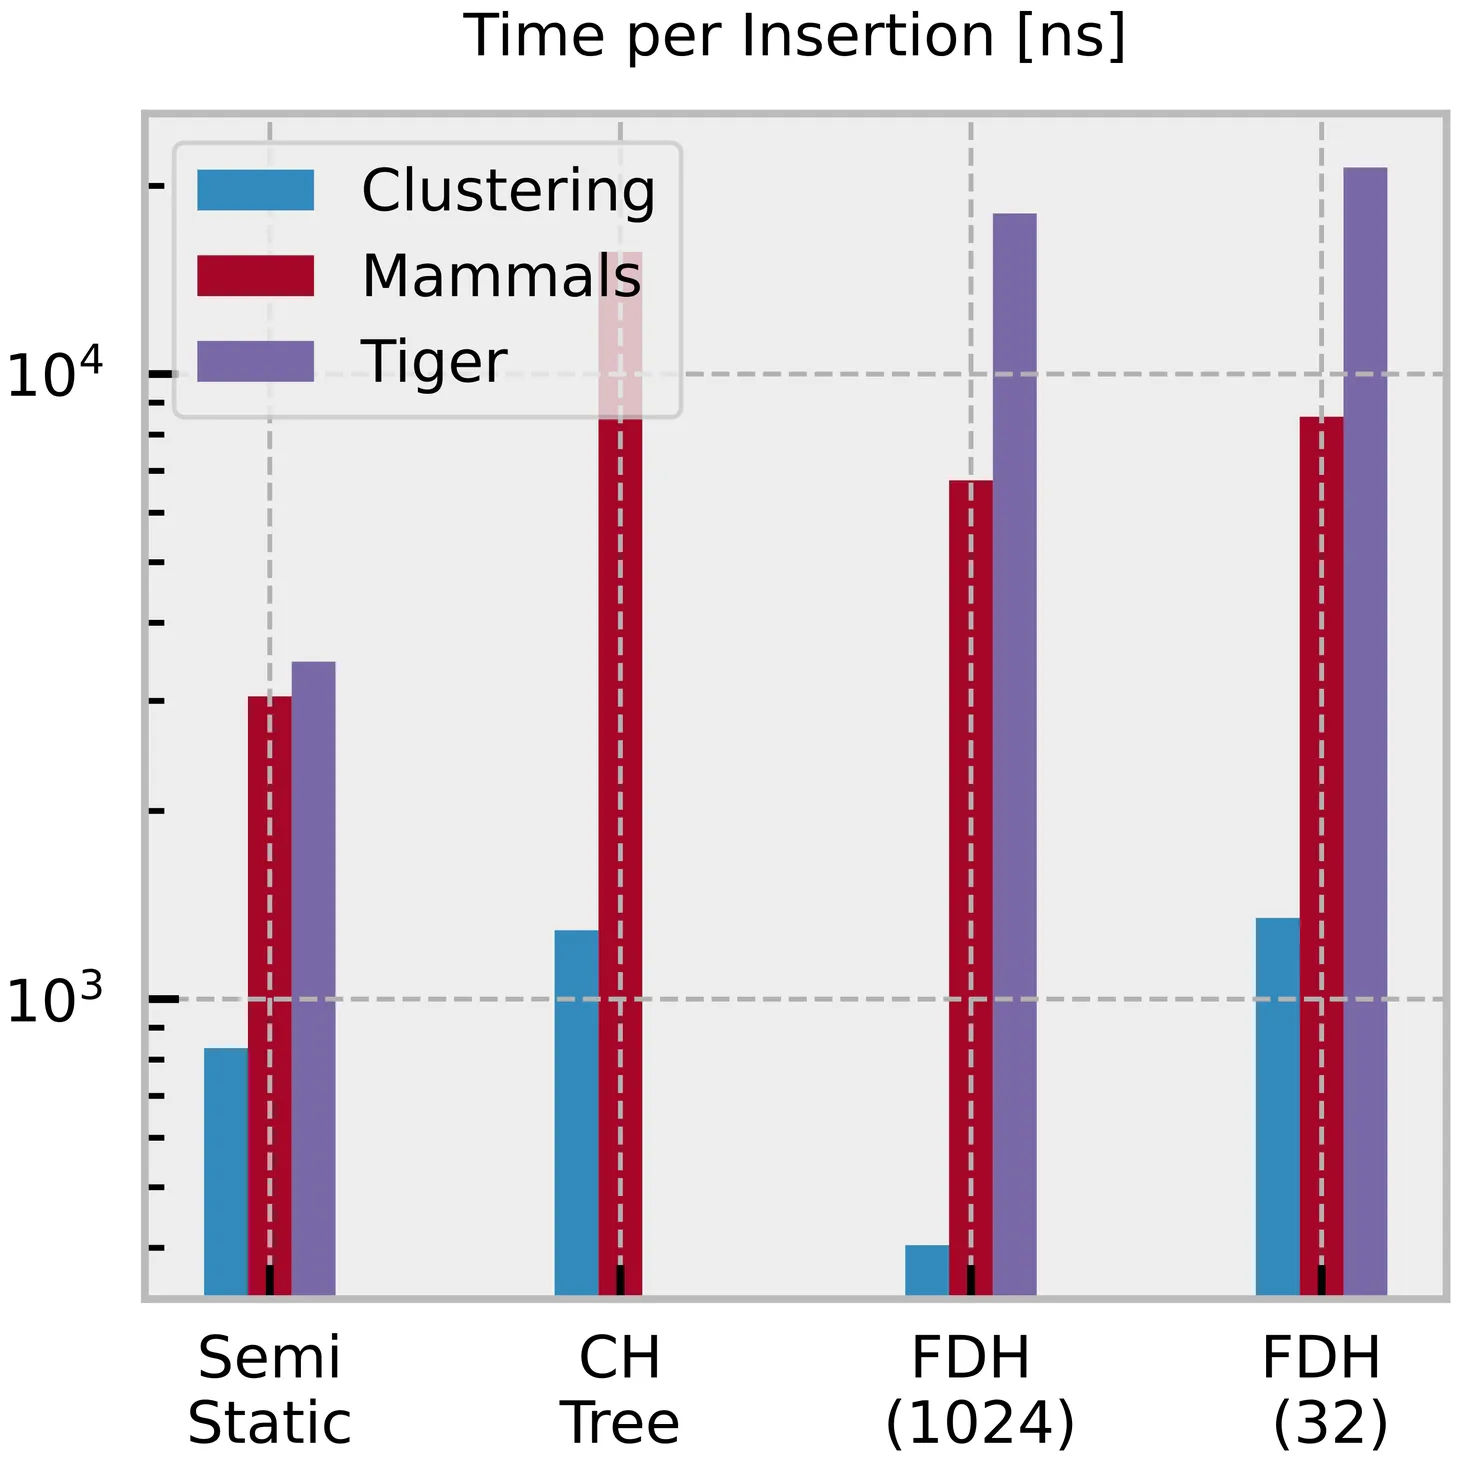
Engineering Fully Dynamic Convex Hulls
We present a new fully dynamic algorithm for maintaining convex hulls under insertions and deletions while supporting geometric queries. Our approach combines the logarithmic method with a deletion-only convex hull data structure, achieving amortised update times of $O(\log n \log \log n)$ and query times of $O(\log^2 n)$. We provide a robust and non-trivial implementation that supports point-location queries, a challenging and non-decomposable class of convex hull queries. We evaluate our implementation against the state of the art, including a new naive baseline that rebuilds the convex hull whenever an update affects it. On hulls that include polynomially many data points (e.g. $Θ(n^\varepsilon)$ for some $\varepsilon$), such as the ones that often occur in practice, our method outperforms all other techniques. Update-heavy workloads strongly favour our approach, which is in line with our theoretical guarantees. Yet, our method remains competitive all the way down to when the update to query ratio is $1$ to $10$. Experiments on real-world data sets furthermore reveal that existing fully dynamic techniques suffer from significant robustness issues. In contrast, our implementation remains stable across all tested inputs.
2604.00271Mar 2026
View2603.29540Computing Topological Transition Sets for Line-Line-Circle Trisectors in $R^3$
Computing the Voronoi diagram of mixed geometric objects in $R^3$ is challenging due to the high cost of exact geometric predicates via Cylindrical Algebraic Decomposition (CAD). We propose an efficient exact verification framework that characterizes the parameter space connectivity by computing certified topological transition sets. We analyze the fundamental non-quadric case: the trisector of two skew lines and one circle in $R^3$. Since the bisectors of circles and lines are not quadric surfaces, the pencil-of-quadrics analysis previously used for the trisectors of three lines is no longer applicable. Our pipeline uses exact symbolic evaluations to identify transition walls. Jacobian computations certify the absence of affine singularities, while projective closure shows singular behavior is isolated at a single point at infinity, $p_{\infty}$. Tangent-cone analysis at $p_{\infty}$ yields a discriminant $Δ_Q = 4ks^2(k-1)$, identifying $k=0,1$ as bifurcation values. Using directional blow-up coordinates, we rigorously verify that the trisector's real topology remains locally constant between these walls. Finally, we certify that $k=0,1$ are actual topological walls exhibiting reducible splitting. This work provides the exact predicates required for constructing mixed-object Voronoi diagrams beyond the quadric-only regime.
2603.29540Mar 2026
View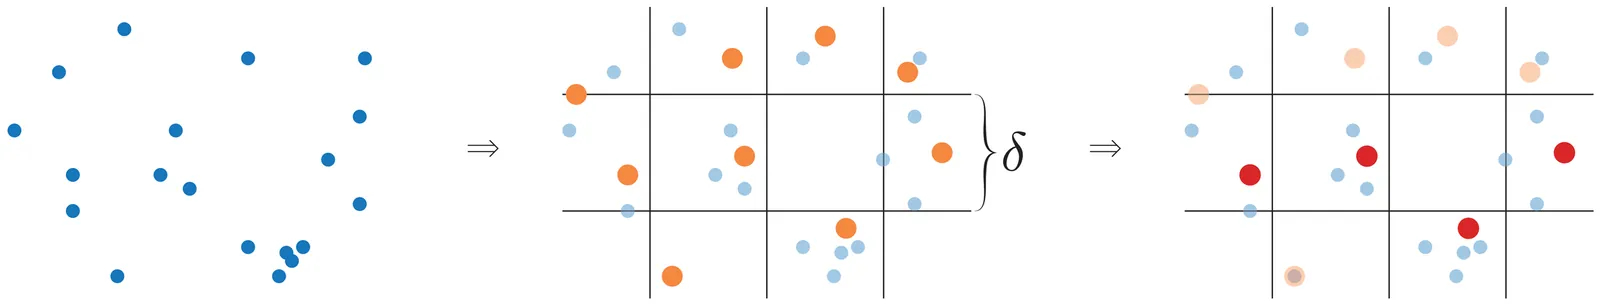
Denoising data reduction algorithm for Topological Data Analysis
Persistent homology is a central tool in topological data analysis, but its application to large and noisy datasets is often limited by computational cost and the presence of spurious topological features. Noise not only increases data size but also obscures the underlying structure of the data. In this paper, we propose the Refined Characteristic Lattice Algorithm (RCLA), a grid-based method that integrates data reduction with threshold-based denoising in a single procedure. By incorporating a threshold parameter $k$, RCLA removes noise while preserving the essential structure of the data in a single pass. We further provide a theoretical guarantee by proving a stability theorem under a homogeneous Poisson noise model, which bounds the bottleneck distance between the persistence diagrams of the output and the underlying shape with high probability. In addition, we introduce an automatic parameter selection method based on nearest-neighbor statistics. Experimental results demonstrate that RCLA consistently outperforms existing methods, and its effectiveness is further validated on a 3D shape classification task.
2603.29248Mar 2026
View2603.28268Near-Optimal Bounds for Parameterized Euclidean k-means
The $k$-means problem is a classic objective for modeling clustering in a metric space. Given a set of points in a metric space, the goal is to find $k$ representative points so as to minimize the sum of the squared distances from each point to its closest representative. In this work, we study the approximability of $k$-means in Euclidean spaces parameterized by the number of clusters, $k$. In seminal works, de la Vega, Karpinski, Kenyon, and Rabani [STOC'03] and Kumar, Sabharwal, and Sen [JACM'10] showed how to obtain a $(1+\varepsilon)$-approximation for high-dimensional Euclidean $k$-means in time $2^{(k/\varepsilon)^{O(1)}} \cdot dn^{O(1)}$. In this work, we introduce a new fine-grained hypothesis called Exponential Time for Expanders Hypothesis (XXH) which roughly asserts that there are no non-trivial exponential time approximation algorithms for the vertex cover problem on near perfect vertex expanders. Assuming XXH, we close the above long line of work on approximating Euclidean $k$-means by showing that there is no $2^{(k/\varepsilon)^{1-o(1)}} \cdot n^{O(1)}$ time algorithm achieving a $(1+\varepsilon)$-approximation for $k$-means in Euclidean space. This lower bound is tight as it matches the algorithm given by Feldman, Monemizadeh, and Sohler [SoCG'07] whose runtime is $2^{\tilde{O}(k/\varepsilon)} + O(ndk)$. Furthermore, assuming XXH, we show that the seminal $O(n^{kd+1})$ runtime exact algorithm of Inaba, Katoh, and Imai [SoCG'94] for $k$-means is optimal for small values of $k$.
2603.28268Mar 2026
View
Fine-Grained Complexity of Continuous Euclidean k-Center
In the (continuous) Euclidean $k$-center problem, given $n$ points in $\mathbb{R}^d$ and an integer $k$, the goal is to find $k$ center points in $\mathbb{R}^d$ that minimize the maximum Euclidean distance from any input point to its closest center. In this paper, we establish conditional lower bounds for this problem in constant dimensions in two settings. $\bullet$ Parameterized by $k$: Assuming the Exponential Time Hypothesis (ETH), we show that there is no $f(k)n^{o(k^{1-1/d})}$-time algorithm for the Euclidean $k$-center problem. This result shows that the algorithm of Agarwal and Procopiuc [SODA 1998; Algorithmica 2002] is essentially optimal. Furthermore, our lower bound rules out any $(1+\varepsilon)$-approximation algorithm running in time $(k/\varepsilon)^{o(k^{1-1/d})}n^{O(1)}$, thereby establishing near-optimality of the corresponding approximation scheme by the same authors. $\bullet$ Small $k$: Assuming the 3-SUM hypothesis, we prove that for any $\varepsilon>0$ there is no $O(n^{2-\varepsilon})$-time algorithm for the Euclidean $2$-center problem in $\mathbb{R}^3$. This settles an open question posed by Agarwal, Ben Avraham, and Sharir [SoCG 2010; Computational Geometry 2013]. In addition, under the same hypothesis, we prove that for any $\varepsilon > 0$, the Euclidean $6$-center problem in $\mathbb{R}^2$ also admits no $O(n^{2-\varepsilon})$-time algorithm. The technical core of all our proofs is a novel geometric embedding of a system of linear equations. We construct a point set where each variable corresponds to a specific collection of points, and the geometric structure ensures that a small-radius clustering is possible if and only if the system has a valid solution.
2603.28265Mar 2026
View
A Polynomial Coreset for Furthest Neighbor in Planar Metrics
A furthest neighbor data structure on a metric space $(V,\mathrm{dist})$ and a set $P \subseteq V$ answers the following query: given $v \in V$, output $p \in P$ maximizing $\mathrm{dist}(v,p)$; in the approximate version, it is allowed to report any $p \in P$ with $\mathrm{dist}(v,p) \geq (1-\varepsilon)\max_{p' \in P} \mathrm{dist}(v,p')$ for an accuracy parameter $\varepsilon \in (0,1)$. A particular type of approximate furthest neighbor data structure is an $\varepsilon$-coreset: a small subset $Q \subseteq P$ such that for every query $v \in V$ there is a feasible answer $p \in Q$. Our main result is that in planar metrics there always exists an $\varepsilon$-coreset for furthest neighbors of size bounded polynomially in $(1/\varepsilon)$. This improves upon an exponential bound of Bourneuf and Pilipczuk [SODA'25] and resolves an open problem of de Berg and Theocharous [SoCG'24] for the case of polygons with holes. On the technical side, we develop a connection between $\varepsilon$-coreset for furthest neighbors and an invariant of a metric space that we call an $\varepsilon$-comatching index -- a sibling of $\varepsilon$-(semi-)ladder index, a.k.a, $\varepsilon$-scatter dimension, as defined by Abbasi et al [FOCS'23]. While the $\varepsilon$-(semi-)ladder index of planar metrics admits an exponential lower bound, we show that the $\varepsilon$-comatching index of planar metrics is polynomial, all in $1/\varepsilon$. The exponential separation between $\varepsilon$-(semi-)ladder and $\varepsilon$-comatching is rather surprising, and the proof is the main technical contribution of our work.
2603.28100Mar 2026
View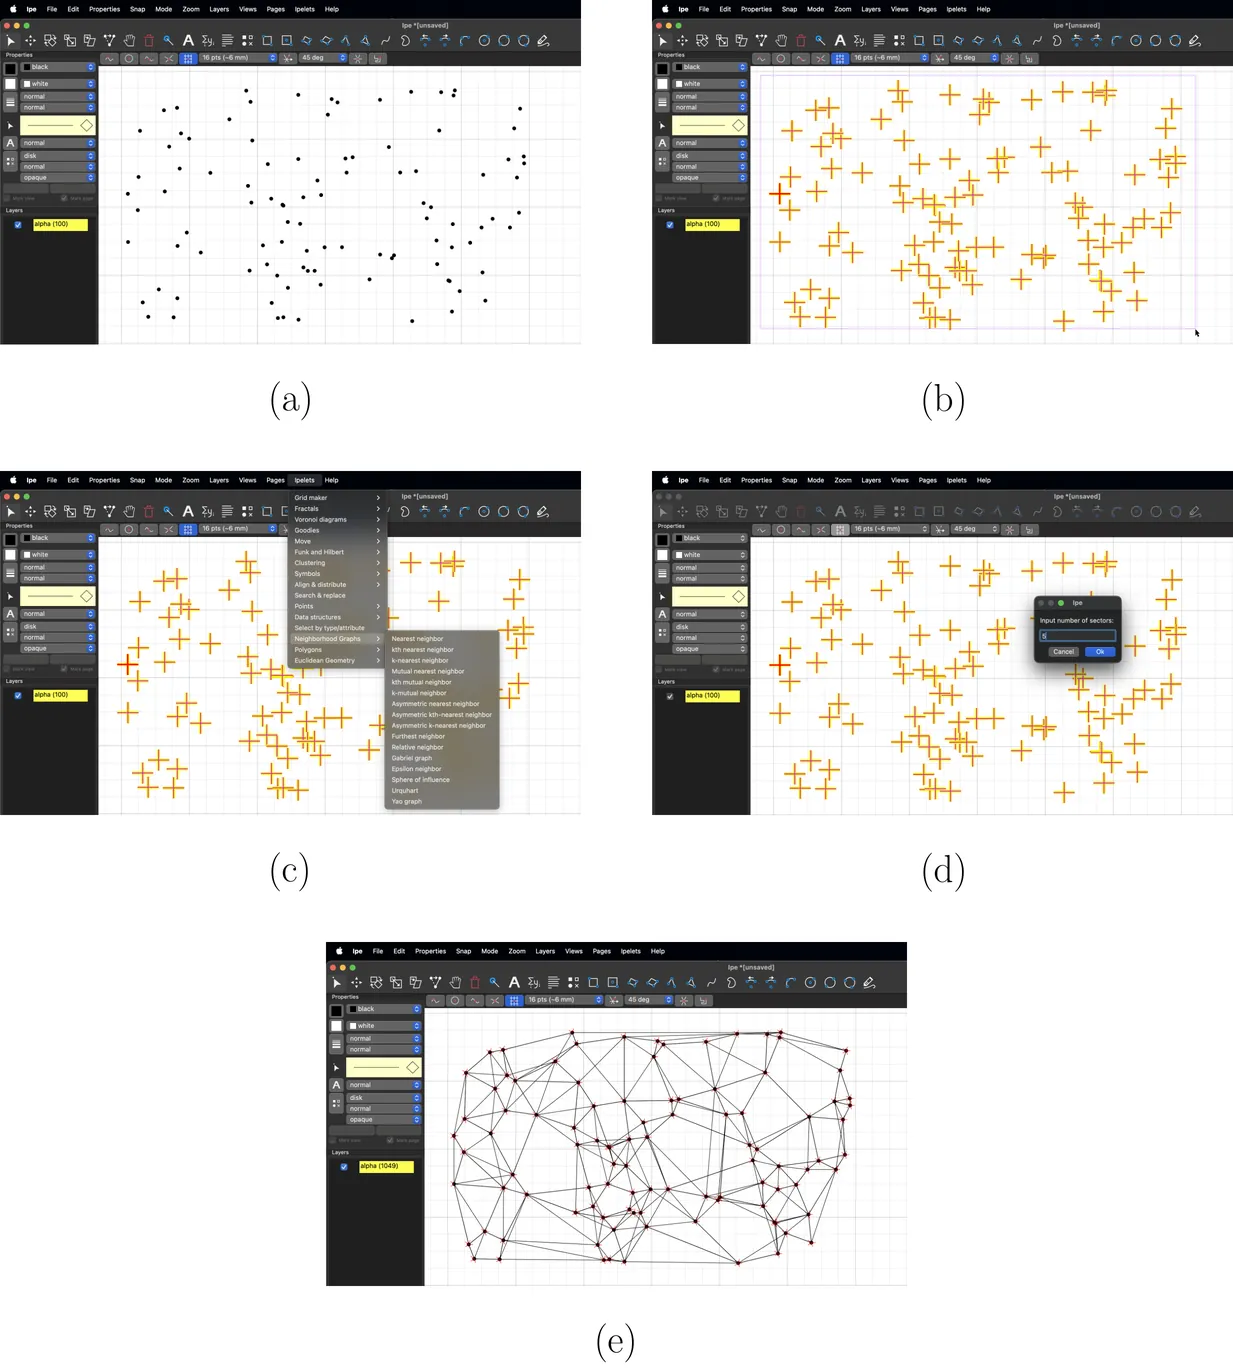
Proximity Alert: Ipelets for Neighborhood Graphs and Clustering
Neighborhood graphs and clustering algorithms are fundamental structures in both computational geometry and data analysis. Visualizing them can help build insight into their behavior and properties. The Ipe extensible drawing editor, developed by Otfried Cheong, is a widely used software system for generating figures. One particular aspect of Ipe is the ability to add Ipelets, which extend its functionality. Here we showcase a set of Ipelets designed to help visualize neighborhood graphs and clustering algorithms. These include: $\eps$-neighbor graphs, furthest-neighbor graphs, Gabriel graphs, $k$-nearest neighbor graphs, $k^{th}$-nearest neighbor graphs, $k$-mutual neighbor graphs, $k^{th}$-mutual neighbor graphs, asymmetric $k$-nearest neighbor graphs, asymmetric $k^{th}$-nearest neighbor graphs, relative-neighbor graphs, sphere-of-influence graphs, Urquhart graphs, Yao graphs, and clustering algorithms including complete-linkage, DBSCAN, HDBSCAN, $k$-means, $k$-means++, $k$-medoids, mean shift, and single-linkage. Our Ipelets are all programmed in Lua and are freely available.
2603.27023Mar 2026
View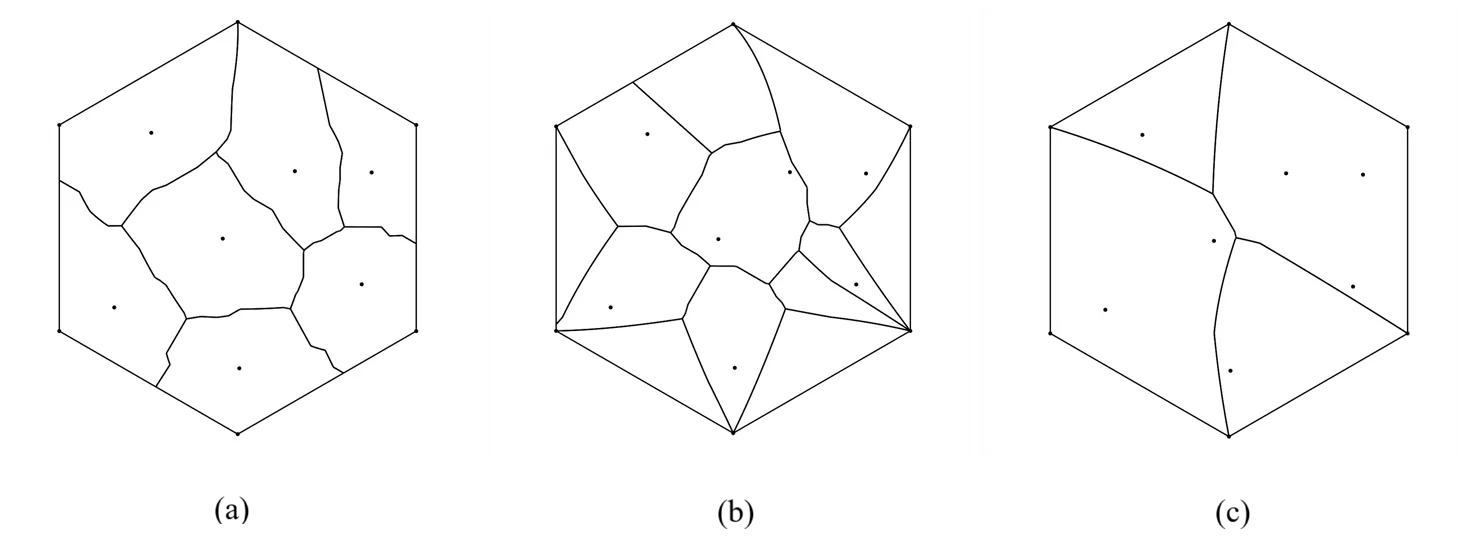
Visualizing Higher Order Structures, Overlap Regions, and Clustering in the Hilbert Geometry
Higher-order Voronoi diagrams and Delaunay mosaics in polygonal metrics have only recently been studied, yet no tools exist for visualizing them. We introduce a tool that fills this gap, providing dynamic interactive software for visualizing higher-order Voronoi diagrams and Delaunay mosaics along with clustering and tools for exploring overlap and outer regions in the Hilbert polygonal metric. We prove that $k^{th}$ order Voronoi cells are not always star-shaped and establish complexity bounds for our algorithm, which generates all order Voronoi diagrams at once. Our software unifies and extends previous tools for visualizing the Hilbert, Funk, and Thompson geometries.
2603.27009Mar 2026
View2603.26964Neural Approximation of Generalized Voronoi Diagrams
We introduce VoroFields, a hierarchical neural-field framework for approximating generalized Voronoi diagrams of finite geometric site sets in low-dimensional domains under arbitrary evaluable point-to-site distances. Instead of constructing the diagram combinatorially, VoroFields learns a continuous, differentiable surrogate whose maximizer structure induces the partition implicitly. The Voronoi cells correspond to maximizer regions of the field, with boundaries defined by equal responses between competing sites. A hierarchical decomposition reduces the combinatorial complexity by refining only near envelope transition strata. Experiments across site families and metrics demonstrate accurate recovery of cells and boundary geometry without shape-specific constructions.
2603.26964Mar 2026
View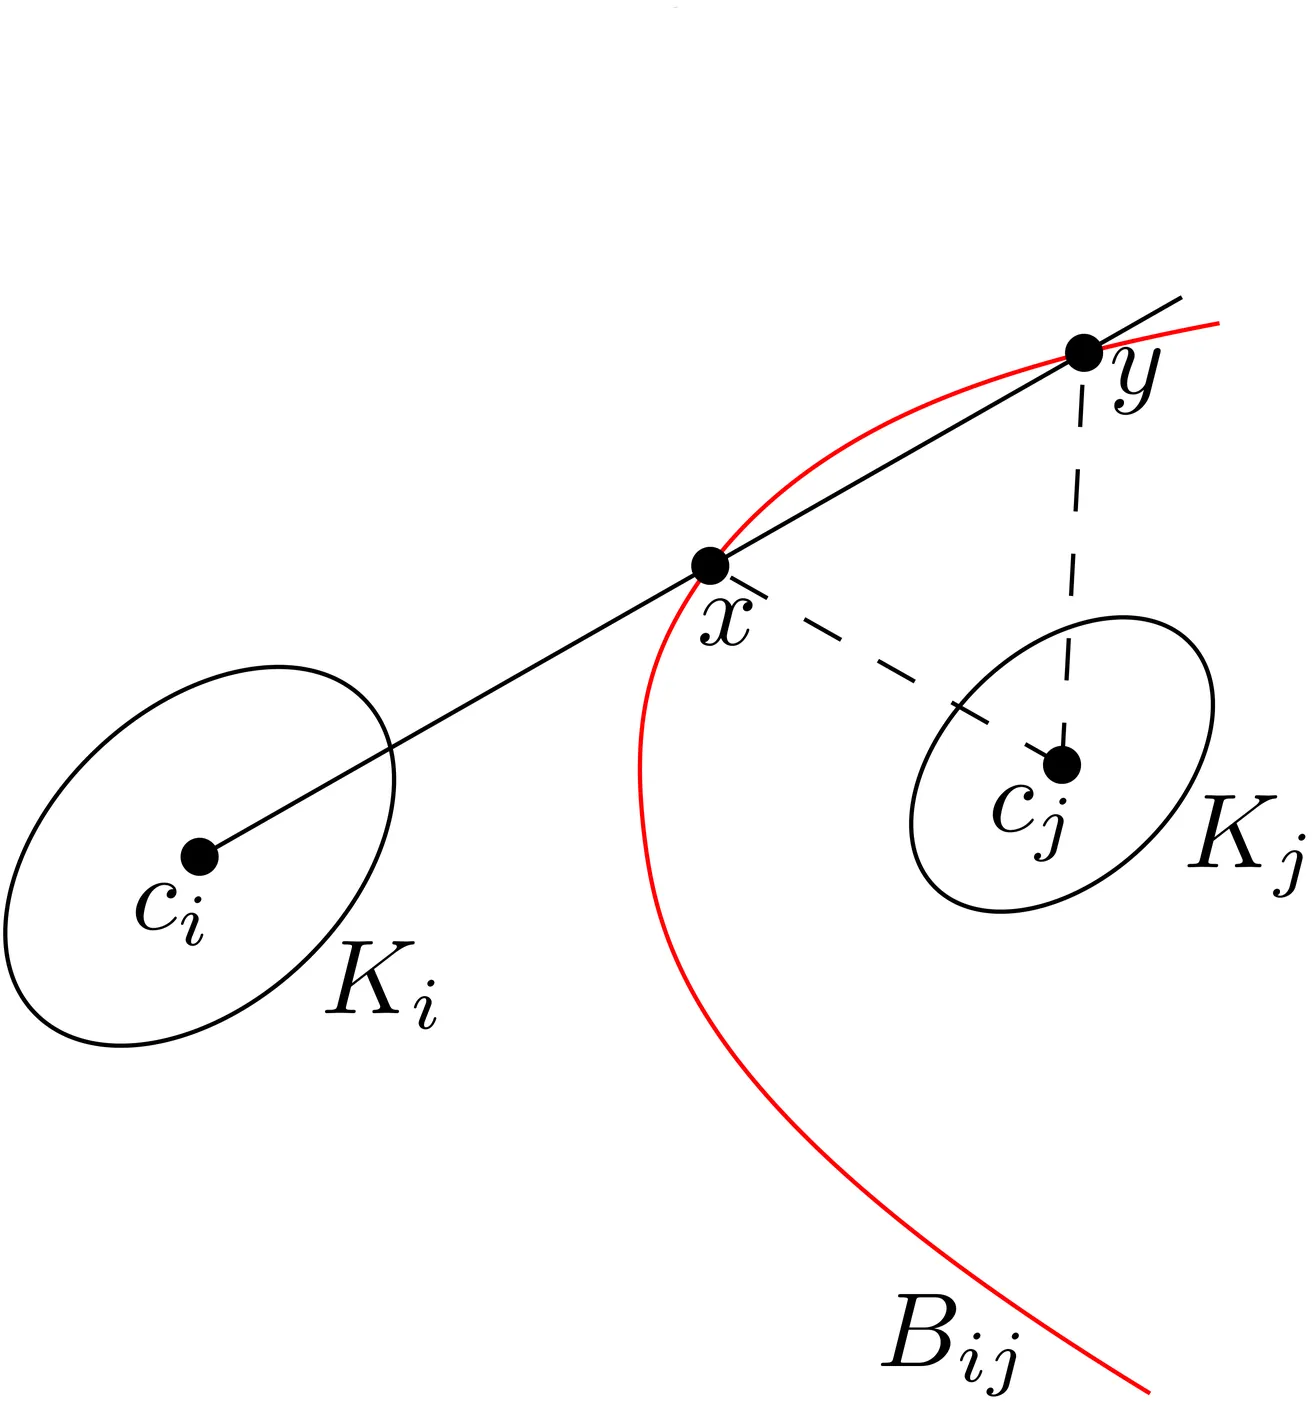
Dynamic Nearest-Neighbor Searching Under General Metrics in ${\mathbb R}^3$ and Its Applications
Let $K$ be a compact, centrally-symmetric, strictly-convex region in ${\mathbb R}^3$, which is a semi-algebraic set of constant complexity, i.e. the unit ball of a corresponding metric, denoted as $\|\cdot\|_K$. Let ${\mathcal{K}}$ be a set of $n$ homothetic copies of $K$. This paper contains two main sets of results: (i) For a storage parameter $s\in[n,n^3]$, ${\mathcal{K}}$ can be preprocessed in $O^*(s)$ expected time into a data structure of size $O^*(s)$, so that for a query homothet $K_0$ of $K$, an intersection-detection query (determine whether $K_0$ intersects any member of ${\mathcal{K}}$, and if so, report such a member) or a nearest-neighbor query (return the member of ${\mathcal{K}}$ whose $\|\cdot\|_K$-distance from $K_0$ is smallest) can be answered in $O^*(n/s^{1/3})$ time; all $k$ homothets of ${\mathcal{K}}$ intersecting $K_0$ can be reported in additional $O(k)$ time. In addition, the data structure supports insertions/deletions in $O^*(s/n)$ amortized expected time per operation. Here the $O^*(\cdot)$ notation hides factors of the form $n^\varepsilon$, where $\varepsilon>0$ is an arbitrarily small constant, and the constant of proportionality depends on $\varepsilon$. (ii) Let $\mathcal{G}(\mathcal{K})$ denote the intersection graph of ${\mathcal{K}}$. Using the above data structure, breadth-first or depth-first search on $\mathcal{G}(\mathcal{K})$ can be performed in $O^*(n^{3/2})$ expected time. Combining this result with the so-called shrink-and-bifurcate technique, the reverse-shortest-path problem in a suitably defined proximity graph of ${\mathcal{K}}$ can be solved in $O^*(n^{62/39})$ expected time. Dijkstra's shortest-path algorithm, as well as Prim's MST algorithm, on a $\|\cdot\|_K$-proximity graph on $n$ points in ${\mathbb R}^3$, with edges weighted by $\|\cdot\|_K$, can also be performed in $O^*(n^{3/2})$ time.
2603.26585Mar 2026
View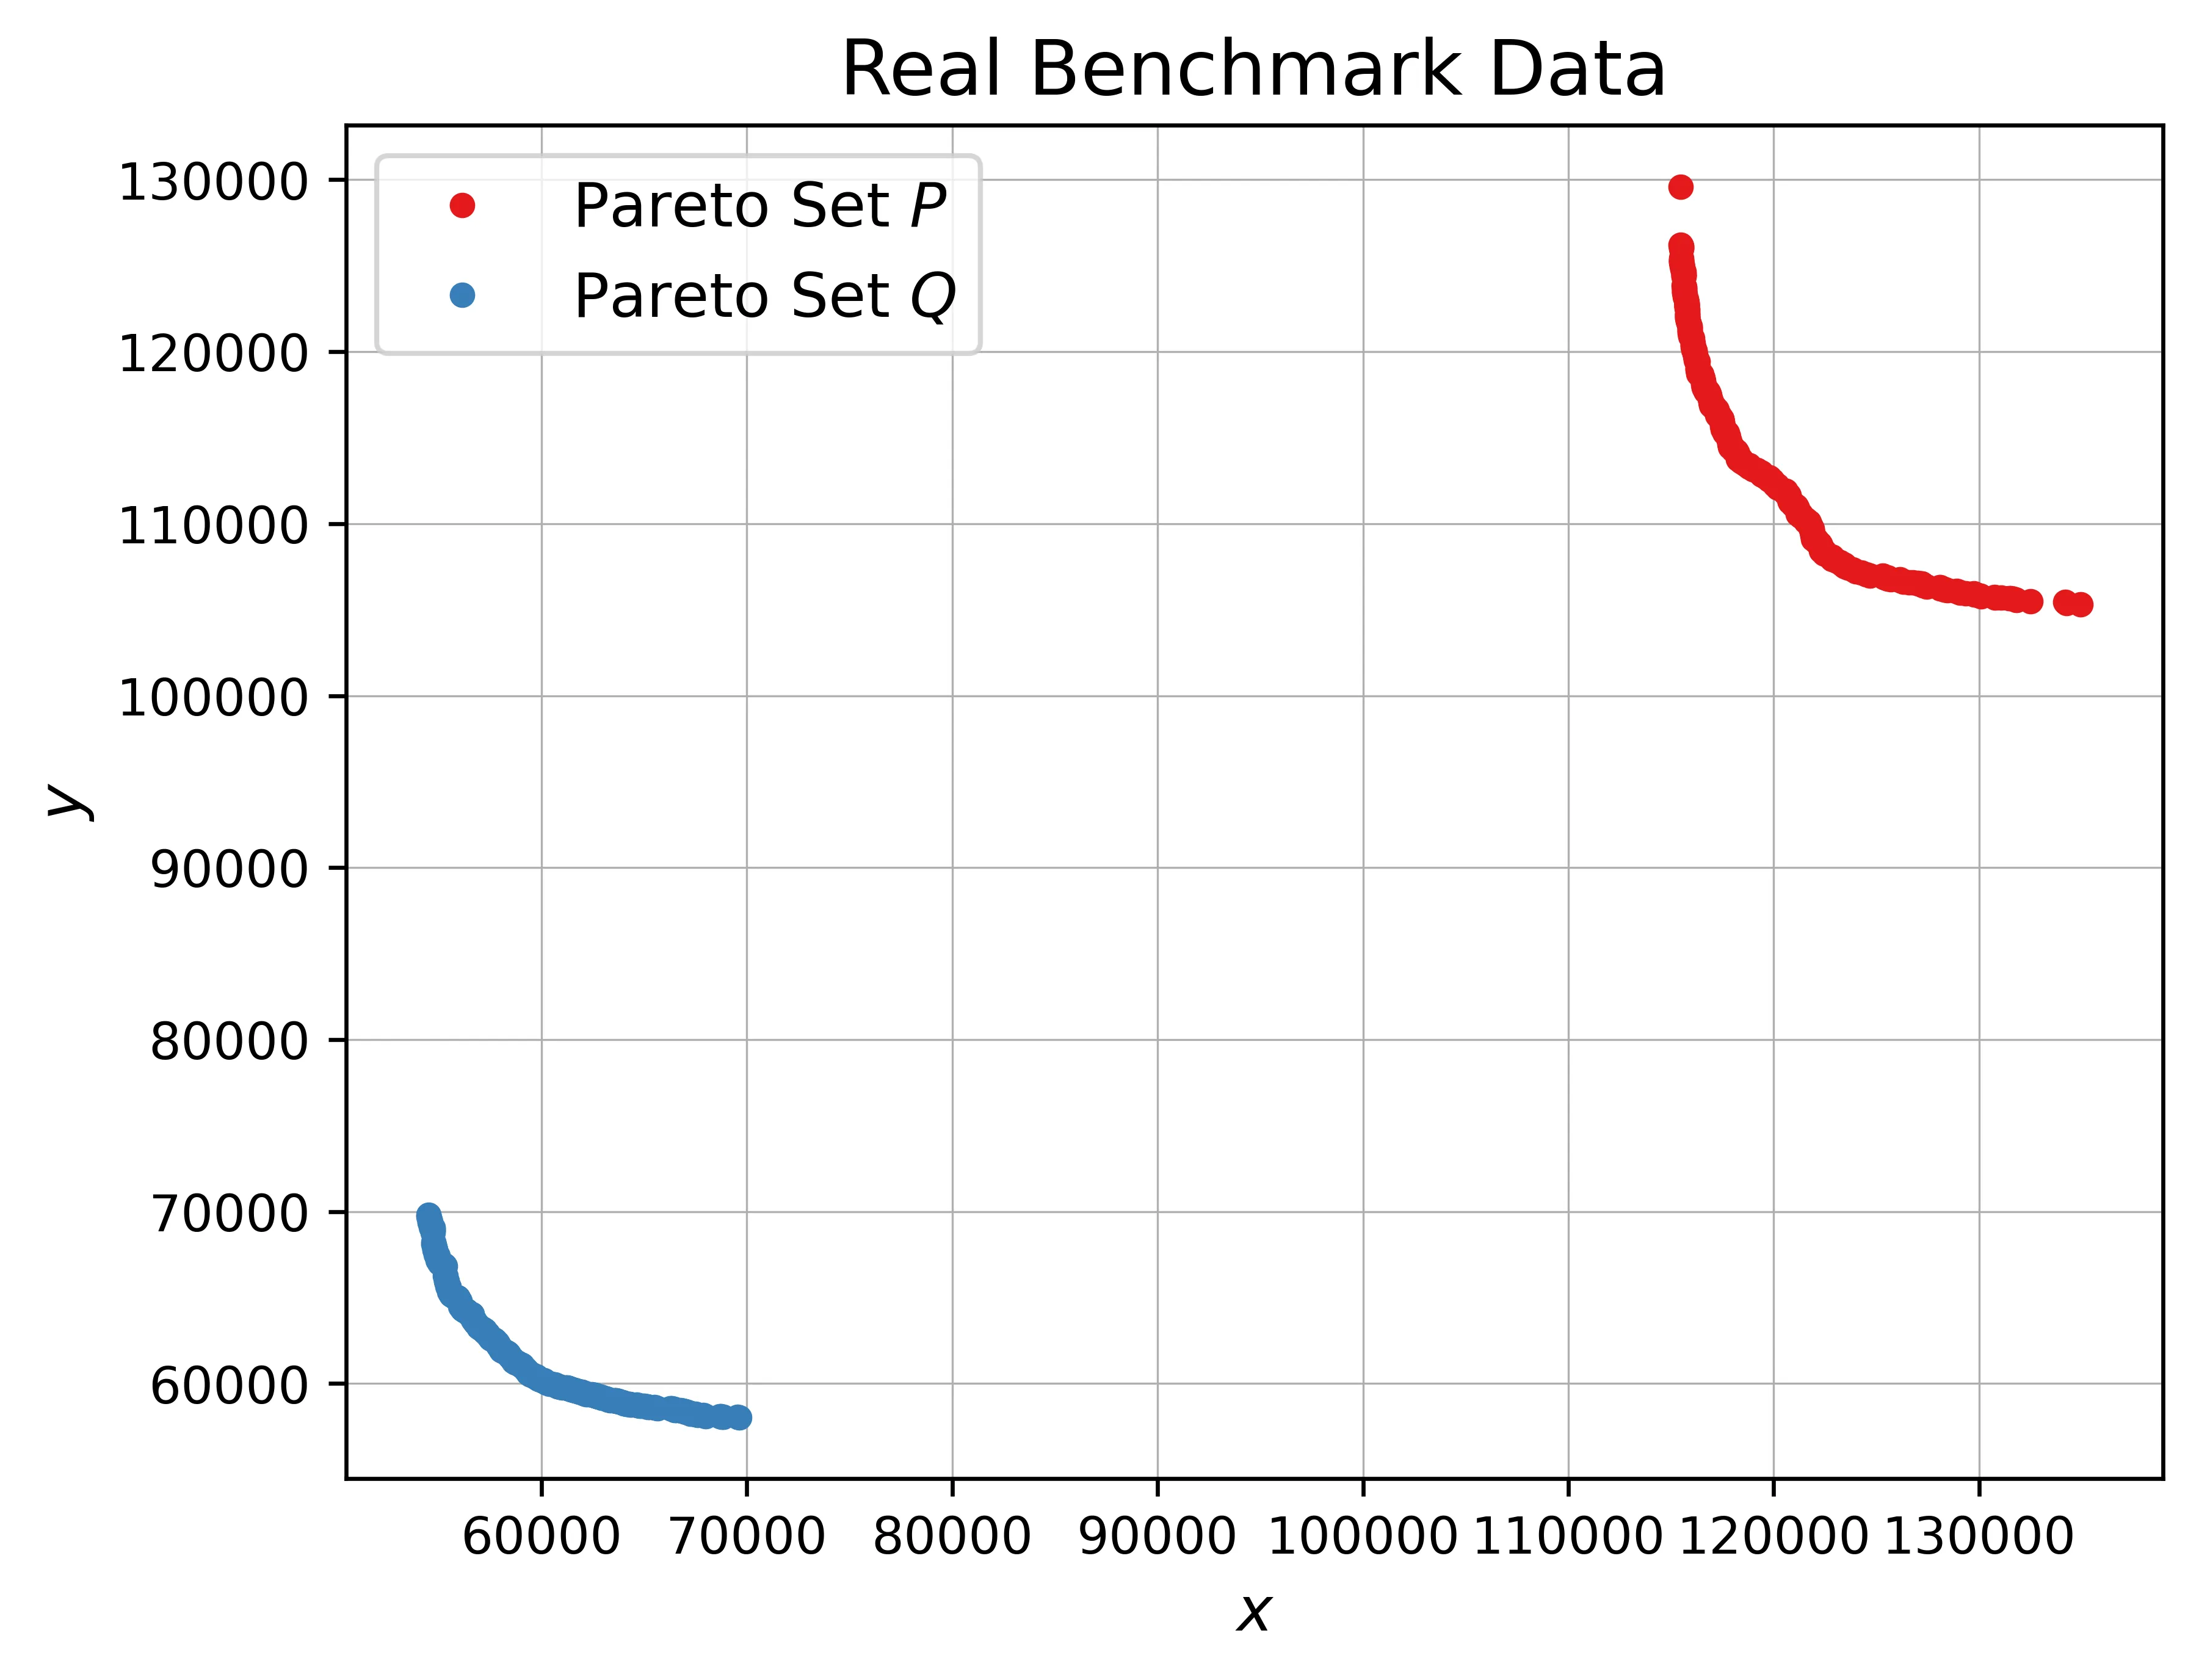
Approximating Pareto Sum via Bounded Monotone Min-Plus Convolution
The Pareto sum of two-dimensional point sets $P$ and $Q$ in $\mathbb{R}^2$ is defined as the skyline of the points in their Minkowski sum. The problem of efficiently computing the Pareto sum arises frequently in bi-criteria optimization algorithms. Prior work establishes that computing the Pareto sum of sets $P$ and $Q$ of size $n$ suffers from conditional lower bounds that rule out strongly subquadratic $O(n^{2-ε})$-time algorithms, even when the output size is $Θ(n)$. Naturally, we ask: How efficiently can we \emph{approximate} Pareto sums, both in theory and practice? Can we beat the near-quadratic-time state of the art for exact algorithms? On the theoretical side, we formulate a notion of additively approximate Pareto sets and show that computing an approximate Pareto set is \emph{fine-grained equivalent} to Bounded Monotone Min-Plus Convolution. Leveraging a remarkable $\tilde{O}(n^{1.5})$-time algorithm for the latter problem (Chi, Duan, Xie, Zhang; STOC '22), we thus obtain a strongly subquadratic (and conditionally optimal) approximation algorithm for computing Pareto sums. On the practical side, we engineer different algorithmic approaches for approximating Pareto sets on realistic instances. Our implementations enable a granular trade-off between approximation quality and running time/output size compared to the state of the art for exact algorithms established in (Funke, Hespe, Sanders, Storandt, Truschel; Algorithmica '25). Perhaps surprisingly, the (theoretical) connection to Bounded Monotone Min-Plus Convolution remains beneficial even for our implementations: in particular, we implement a simplified, yet still subquadratic version of an algorithm due to Chi, Duan, Xie and Zhang, which on some sufficiently large instances outperforms the competing quadratic-time approaches.
2603.25449Mar 2026
View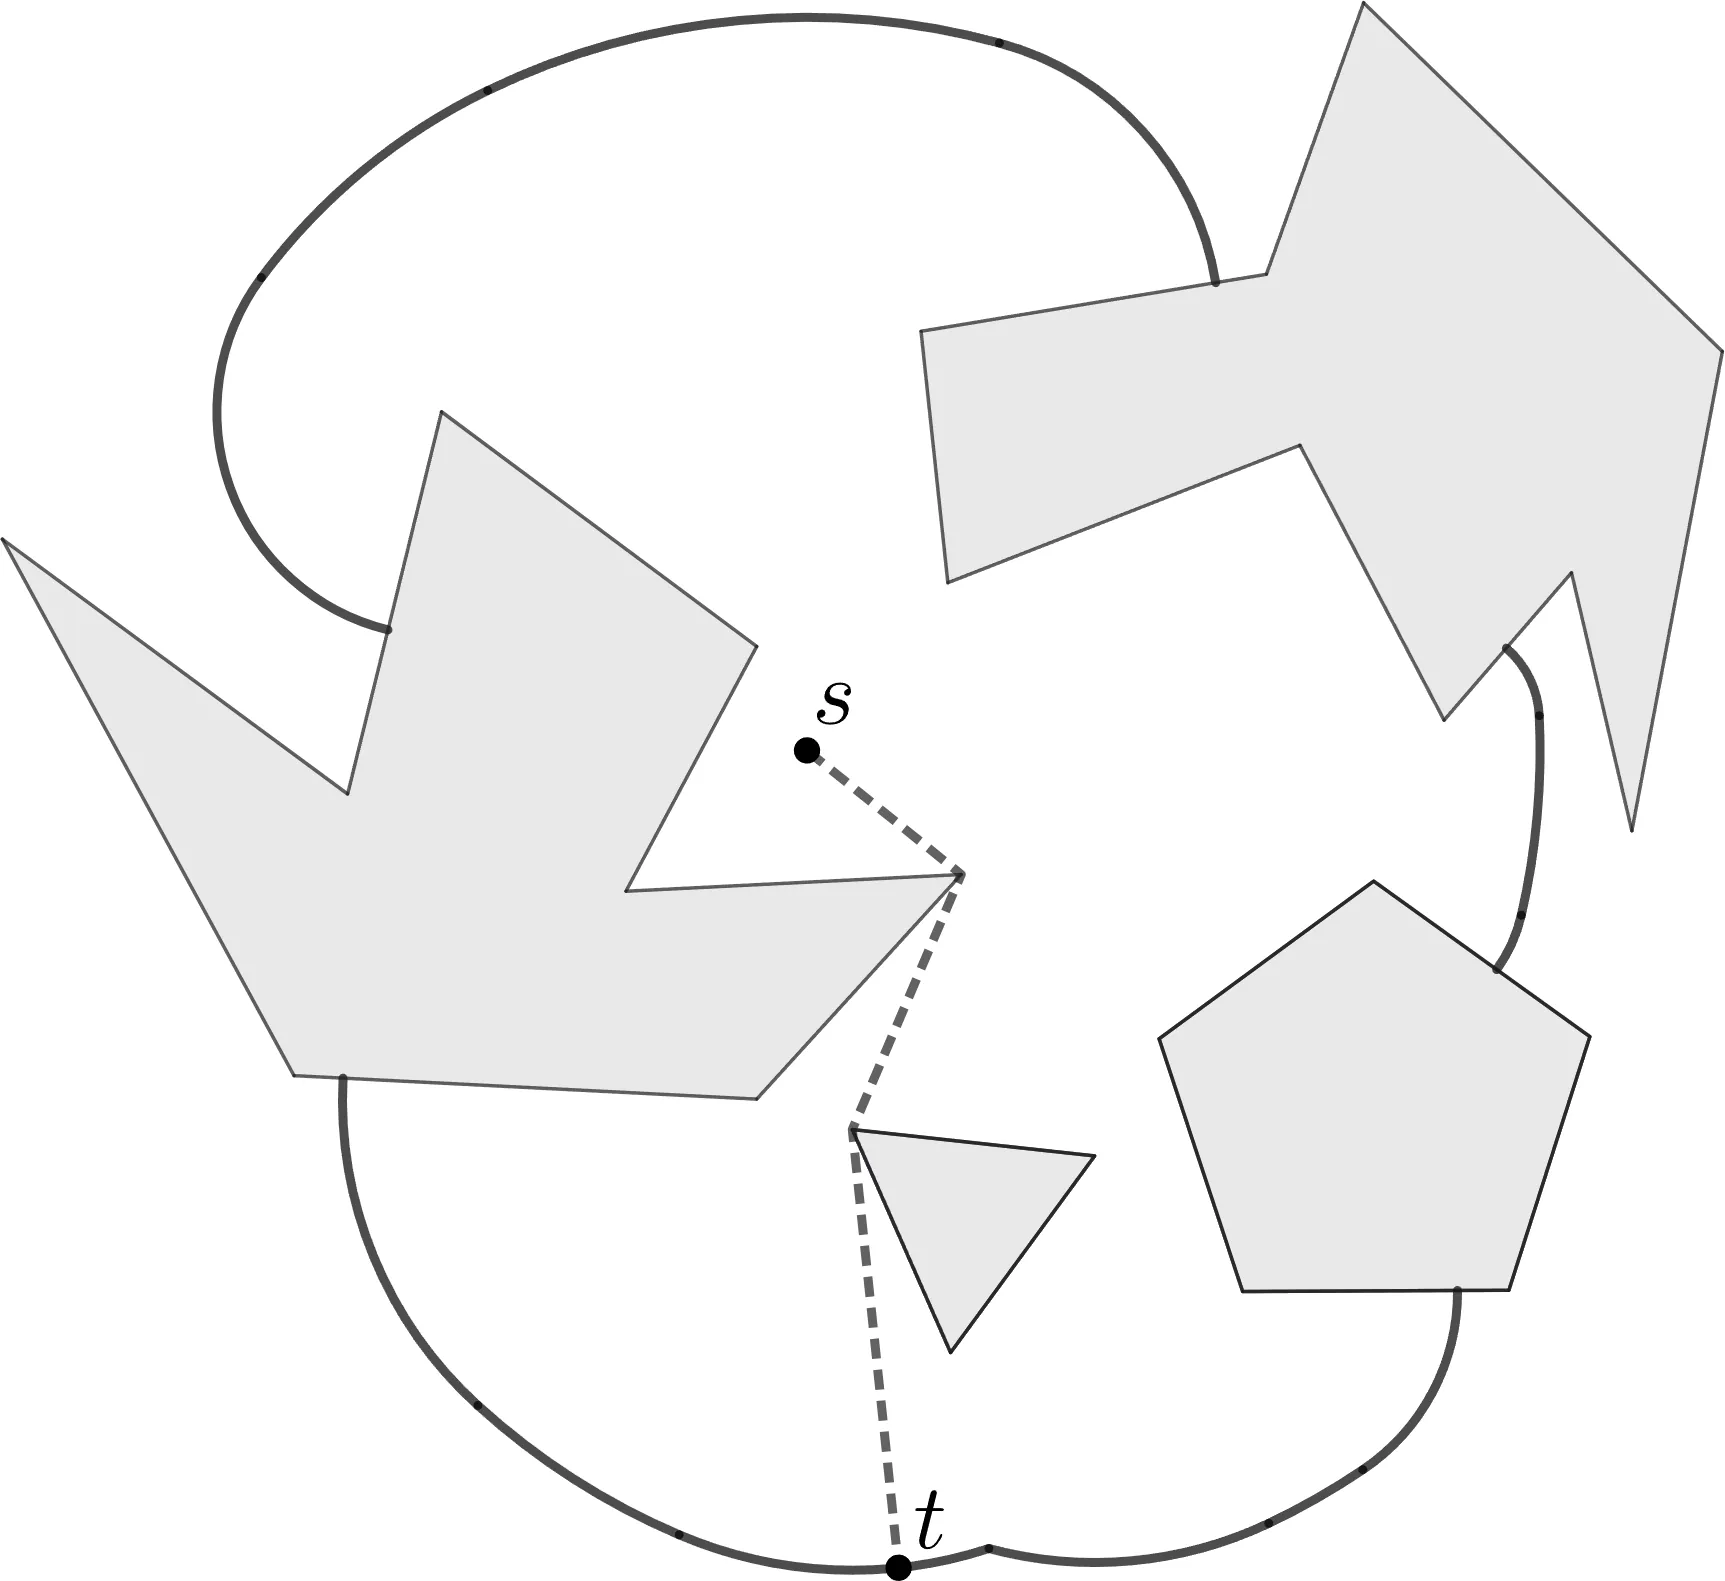
Shortest Paths in Geodesic Unit-Disk Graphs
Let $S$ be a set of $n$ points in a polygon $P$ with $m$ vertices. The geodesic unit-disk graph $G(S)$ induced by $S$ has vertex set $S$ and contains an edge between two vertices whenever their geodesic distance in $P$ is at most one. In the weighted version, each edge is assigned weight equal to the geodesic distance between its endpoints; in the unweighted version, every edge has weight $1$. Given a source point $s \in S$, we study the problem of computing shortest paths from $s$ to all vertices of $G(S)$. To the best of our knowledge, this problem has not been investigated previously. A naive approach constructs $G(S)$ explicitly and then applies a standard shortest path algorithm for general graphs, but this requires quadratic time in the worst case, since $G(S)$ may contain $Ω(n^2)$ edges. In this paper, we give the first subquadratic-time algorithms for this problem. For the weighted case, when $P$ is a simple polygon, we obtain an $O(m + n \log^{2} n \log^{2} m)$-time algorithm. For the unweighted case, we provide an $O(m + n \log n \log^{2} m)$-time algorithm for simple polygons, and an $O(\sqrt{n} (n+m)\log(n+m))$-time algorithm for polygons with holes. To achieve these results, we develop a data structure for deletion-only geodesic unit-disk range emptiness queries, as well as a data structure for constructing implicit additively weighted geodesic Voronoi diagrams in simple polygons. In addition, we propose a dynamic data structure that extends Bentley's logarithmic method from insertions to priority-queue updates, namely insertion and delete-min operations. These results may be of independent interest.
2603.24872Mar 2026
View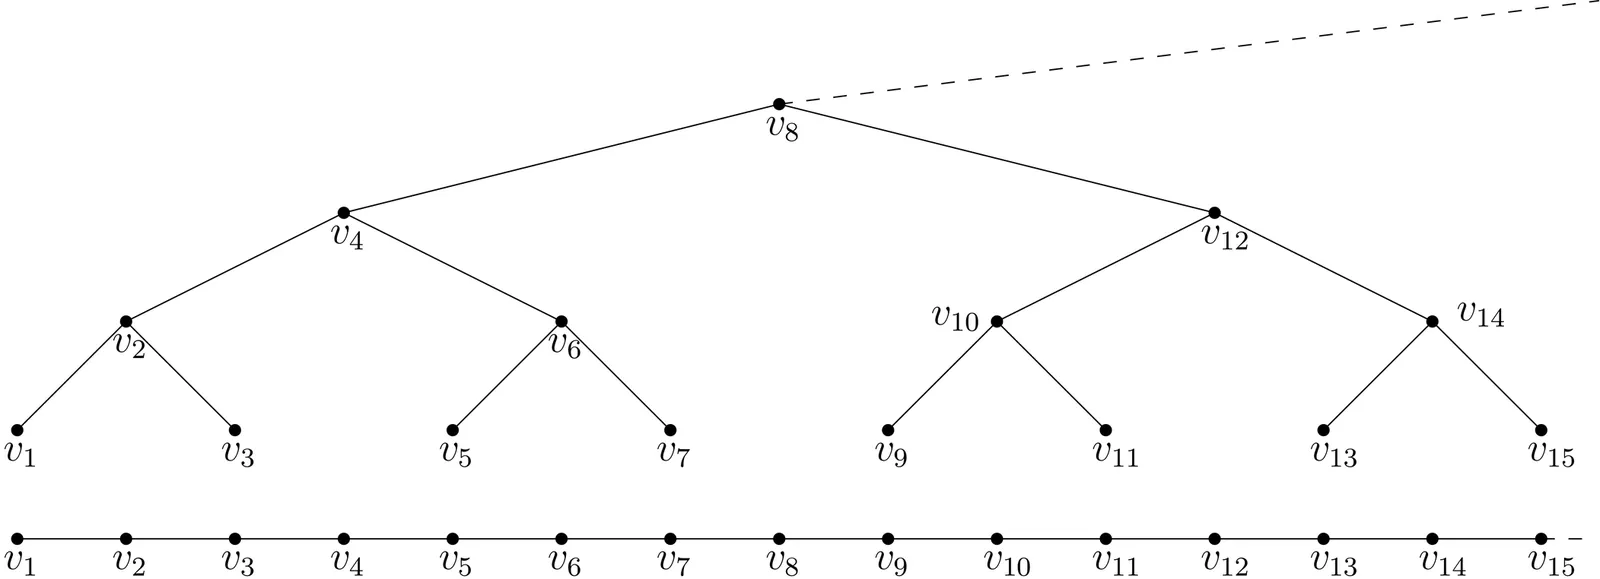
Dynamic Light Spanners in Doubling Metrics
A $t$-spanner of a point set $X$ in a metric space $(\mathcal{X}, δ)$ is a graph $G$ with vertex set $P$ such that, for any pair of points $u,v \in X$, the distance between $u$ and $v$ in $G$ is at most $t$ times $δ(u,v)$. We study the problem of maintaining a spanner for a dynamic point set $X$ -- that is, when $X$ undergoes a sequence of insertions and deletions -- in a metric space of constant doubling dimension. For any constant $\varepsilon>0$, we maintain a $(1+\varepsilon)$-spanner of $P$ whose total weight remains within a constant factor of the weight of the minimum spanning tree of $X$. Each update (insertion or deletion) can be performed in $\operatorname{poly}(\log Φ)$ time, where $Φ$ denotes the aspect ratio of $X$. Prior to our work, no efficient dynamic algorithm for maintaining a light-weight spanner was known even for point sets in low-dimensional Euclidean space.
2603.23490Mar 2026
View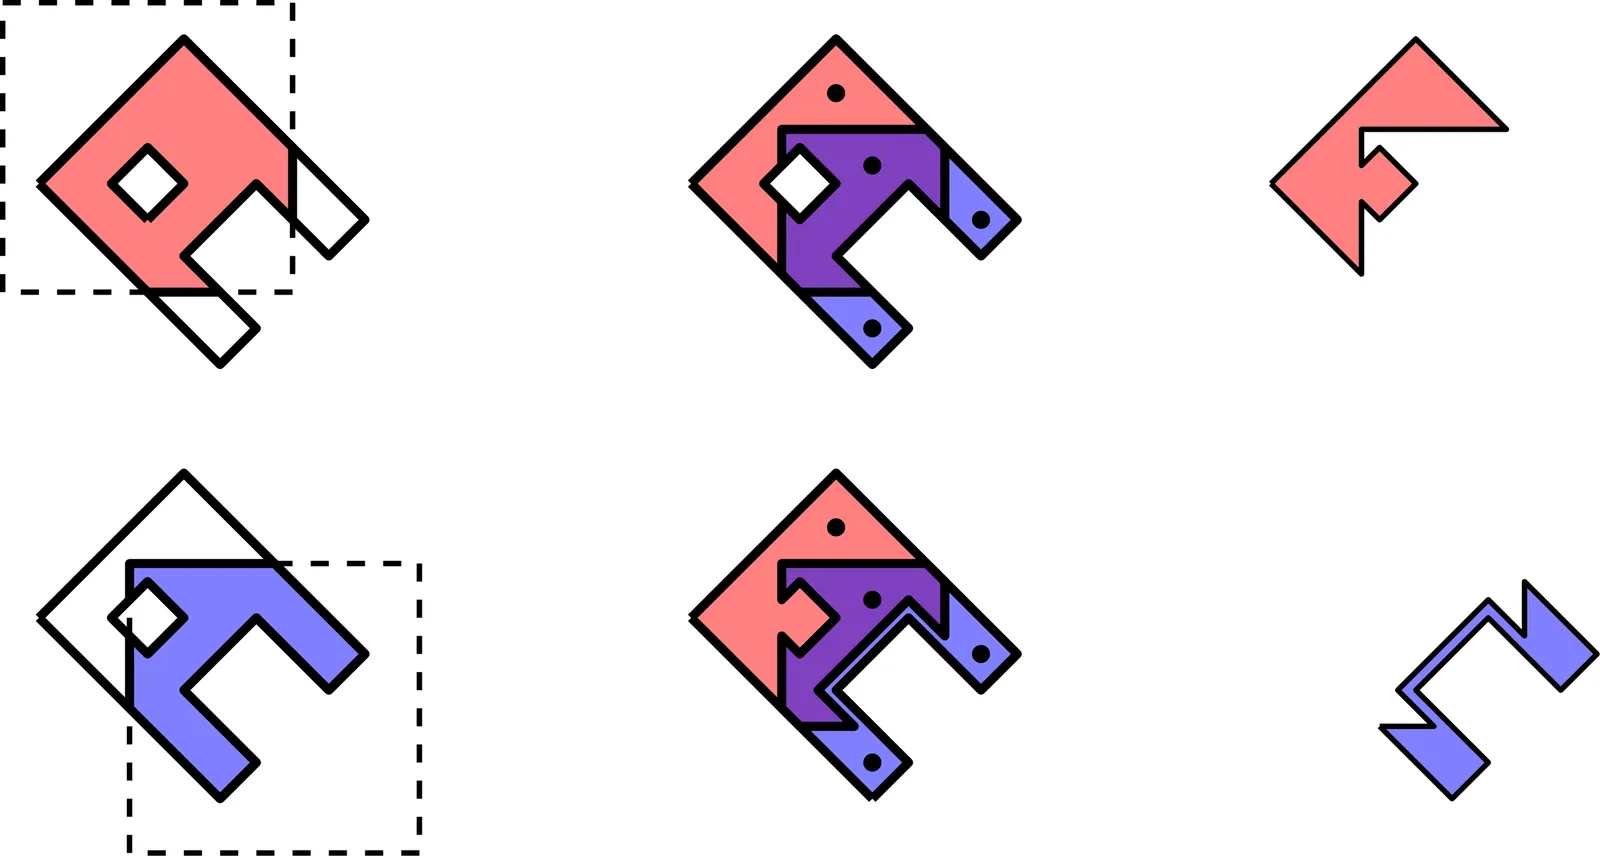
Covering and Partitioning Complex Objects with Small Pieces
We study the problems of covering or partitioning a polygon $P$ (possibly with holes) using a minimum number of small pieces, where a small piece is a connected sub-polygon contained in an axis-aligned unit square. For covering, we seek to write $P$ as a union of small pieces, and in partitioning, we furthermore require the pieces to be pairwise interior-disjoint. We show that these problems are in fact equivalent: Optimum covers and partitions have the same number of pieces. For covering, a natural local search algorithm repeatedly attempts to replace $k$ pieces from a candidate cover with $k-1$ pieces. In two dimensions and for sufficiently large $k$, we show that when no such swap is possible, the cover is a $1+O(1/\sqrt k)$-approximation, hence obtaining the first PTAS for the problem. Prior to our work, the only known algorithm was a $13$-approximation that only works for polygons without holes [Abrahamsen and Rasmussen, SODA 2025]. In contrast, in the three dimensional version of the problem, for a polyhedron $P$ of complexity $n$, we show that it is NP-hard to approximate an optimal cover or partition to within a factor that is logarithmic in $n$, even if $P$ is simple, i.e., has genus $0$ and no holes.
2603.23216Mar 2026
View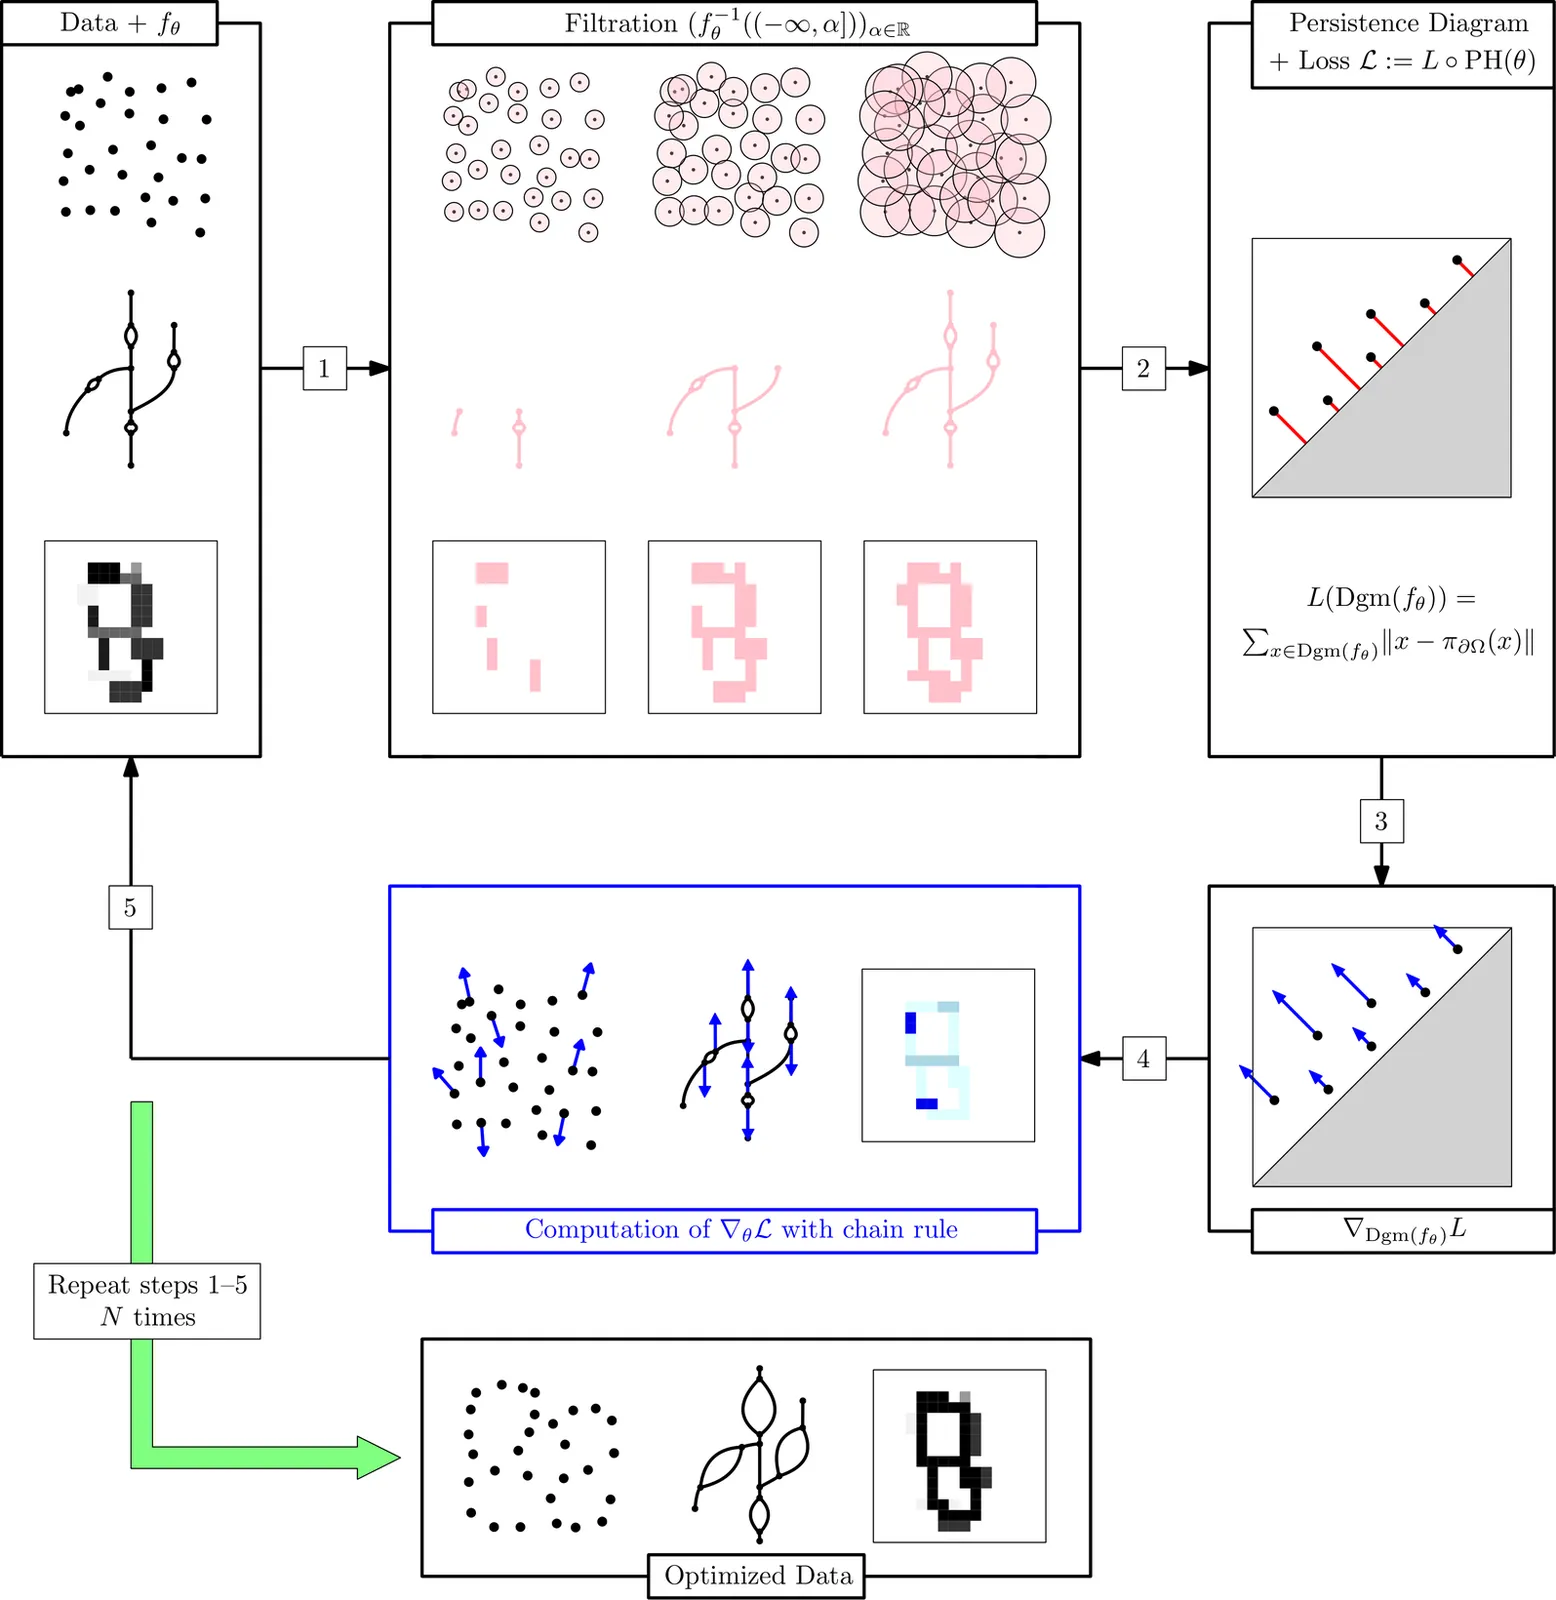
Persistence-based topological optimization: a survey
Computational topology provides a tool, persistent homology, to extract quantitative descriptors from structured objects (images, graphs, point clouds, etc). These descriptors can then be involved in optimization problems, typically as a way to incorporate topological priors or to regularize machine learning models. This is usually achieved by minimizing adequate, topologically-informed losses based on these descriptors, which, in turn, naturally raises theoretical and practical questions about the possibility of optimizing such loss functions using gradient-based algorithms. This has been an active research field in the topological data analysis community over the last decade, and various techniques have been developed to enable optimization of persistence-based loss functions with gradient descent schemes. This survey presents the current state of this field, covering its theoretical foundations, the algorithmic aspects, and showcasing practical uses in several applications. It includes a detailed introduction to persistence theory and, as such, aims at being accessible to mathematicians and data scientists newcomers to the field. It is accompanied by an open-source library which implements the different approaches covered in this survey, providing a convenient playground for researchers to get familiar with the field.
2603.24613Mar 2026
View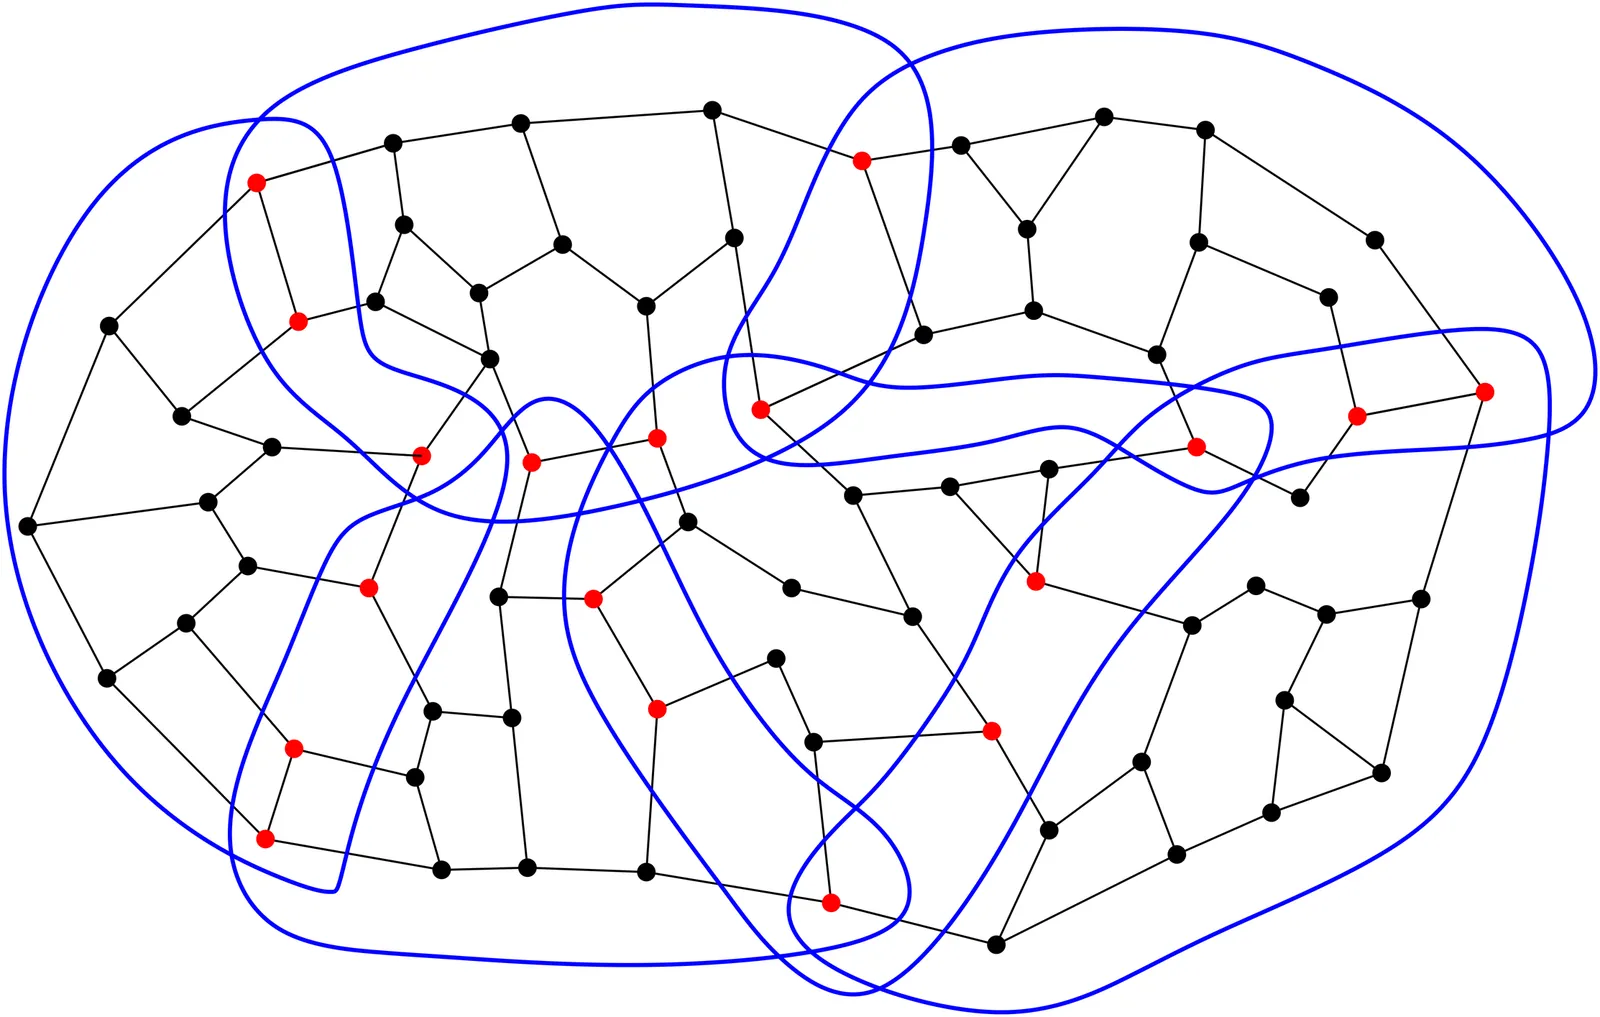
Linear time single-source shortest path algorithms in Euclidean graph classes
In the celebrated paper of Henzinger, Klein, Rao and Subramanian (1997), it was shown that planar graphs admit a linear time single-source shortest path algorithm. Their algorithm unfortunately does not extend to Euclidean graph classes. We give criteria and prove that any Euclidean graph class satisfying the criteria admits a linear time single-source shortest path algorithm. As a main ingredient, we show that the contracted graphs of these Euclidean graph classes admit sublinear separators.
2603.22948Mar 2026
ViewPage 1 of 40