620 papers
Hierarchical Semantic Correlation-Aware Masked Autoencoder for Unsupervised Audio-Visual Representation Learning
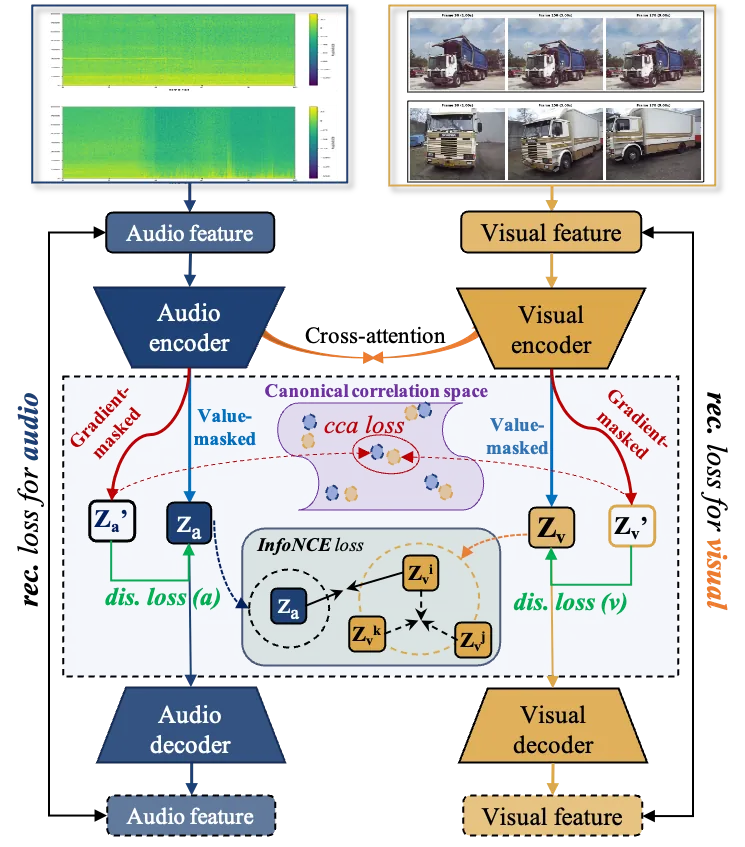
Learning aligned multimodal embeddings from weakly paired, label-free corpora is challenging: pipelines often provide only pre-extracted features, clips contain multiple events, and spurious co-occurrences. We propose HSC-MAE (Hierarchical Semantic Correlation-Aware Masked Autoencoder), a dual-path teacher-student framework that enforces semantic consistency across three complementary levels of representation - from coarse to fine: (i) global-level canonical-geometry correlation via DCCA, which aligns audio and visual embeddings within a shared modality-invariant subspace; (ii) local-level neighborhood-semantics correlation via teacher-mined soft top-k affinities, which preserves multi-positive relational structure among semantically similar instances; and (iii) sample-level conditional-sufficiency correlation via masked autoencoding, which ensures individual embeddings retain discriminative semantic content under partial observation. Concretely, a student MAE path is trained with masked feature reconstruction and affinity-weighted soft top-k InfoNCE; an EMA teacher operating on unmasked inputs via the CCA path supplies stable canonical geometry and soft positives. Learnable multi-task weights reconcile competing objectives, and an optional distillation loss transfers teacher geometry into the student. Experiments on AVE and VEGAS demonstrate substantial mAP improvements over strong unsupervised baselines, validating that HSC-MAE yields robust and well-structured audio-visual representations.
2604.04229Apr 2026
View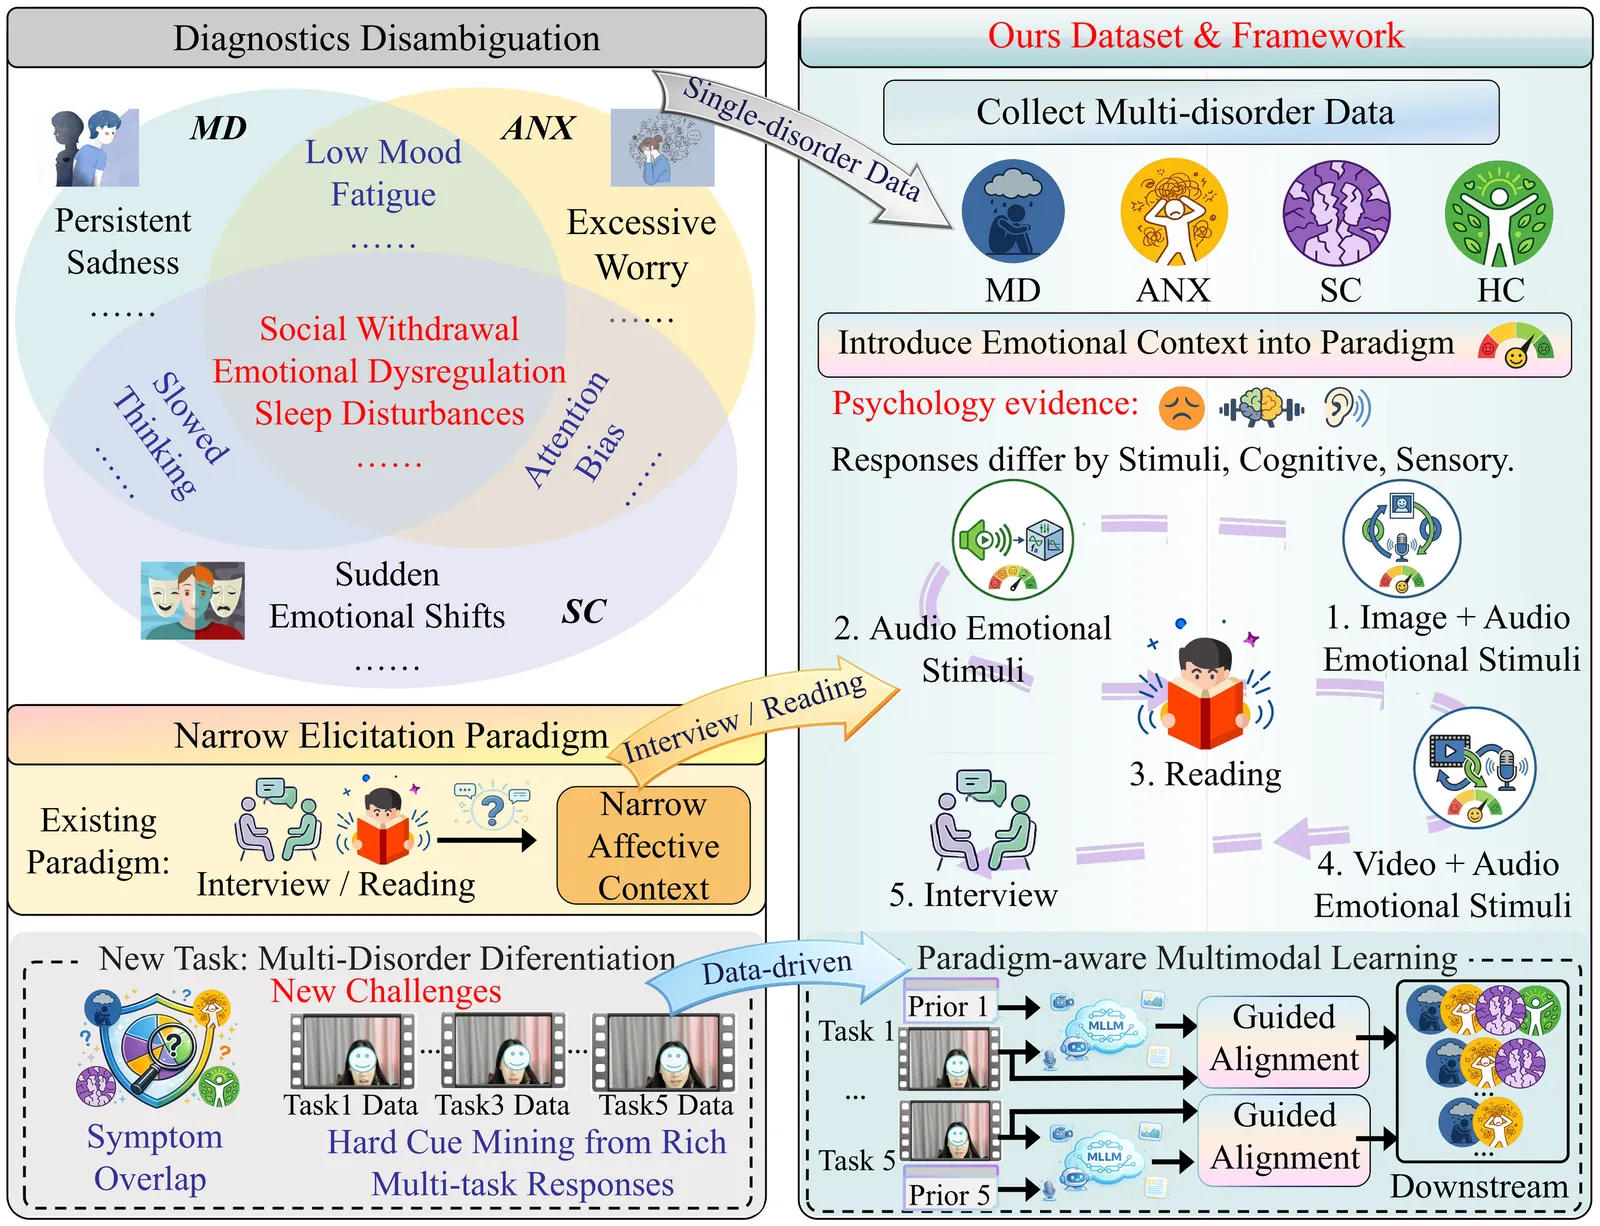
Differential Mental Disorder Detection with Psychology-Inspired Multimodal Stimuli
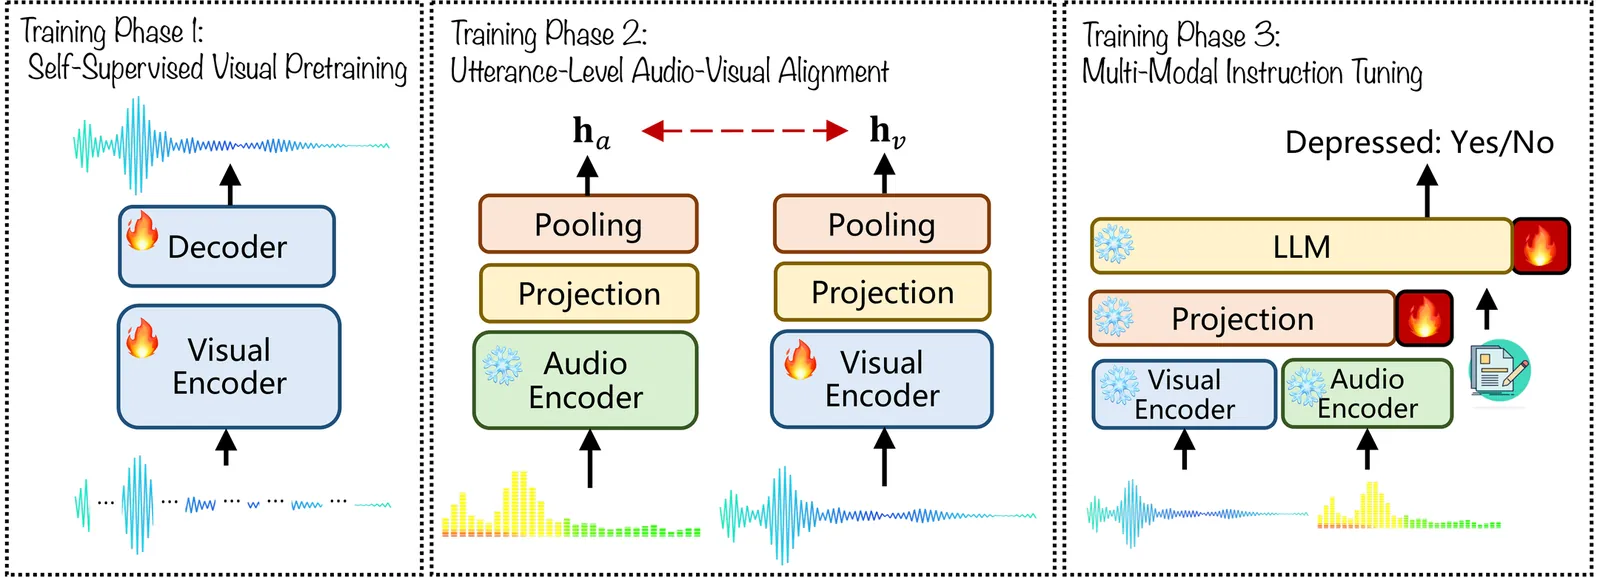
Differential diagnosis of mental disorders remains a fundamental challenge in real-world clinical practice, where multiple conditions often exhibit overlapping symptoms. However, most existing public datasets are developed under single-disorder settings and rely on limited data elicitation paradigms, restricting their ability to capture disorder-specific patterns. In this work, we investigate differential mental disorder detection through psychology-inspired multimodal stimuli, designed to elicit diverse emotional, cognitive, and behavioral responses grounded in findings from experimental psychology. Based on this paradigm, we collect a large-scale multimodal mental health dataset (MMH) covering depression, anxiety, and schizophrenia, with all diagnostic labels clinically verified by licensed psychiatrists. To effectively model the heterogeneous signals induced by diverse elicitation tasks, we further propose a paradigm-aware multimodal framework that leverages inter-disorder differences prior knowledge as prompt-guided semantic descriptions to capture task-specific affective and interaction contexts for multimodal representation learning in the new differential mental disorder detection task. Extensive experiments show that our framework consistently outperforms existing baselines, underscoring the value of psychology-inspired stimulus design for differential mental disorder detection.
2604.02798Apr 2026
View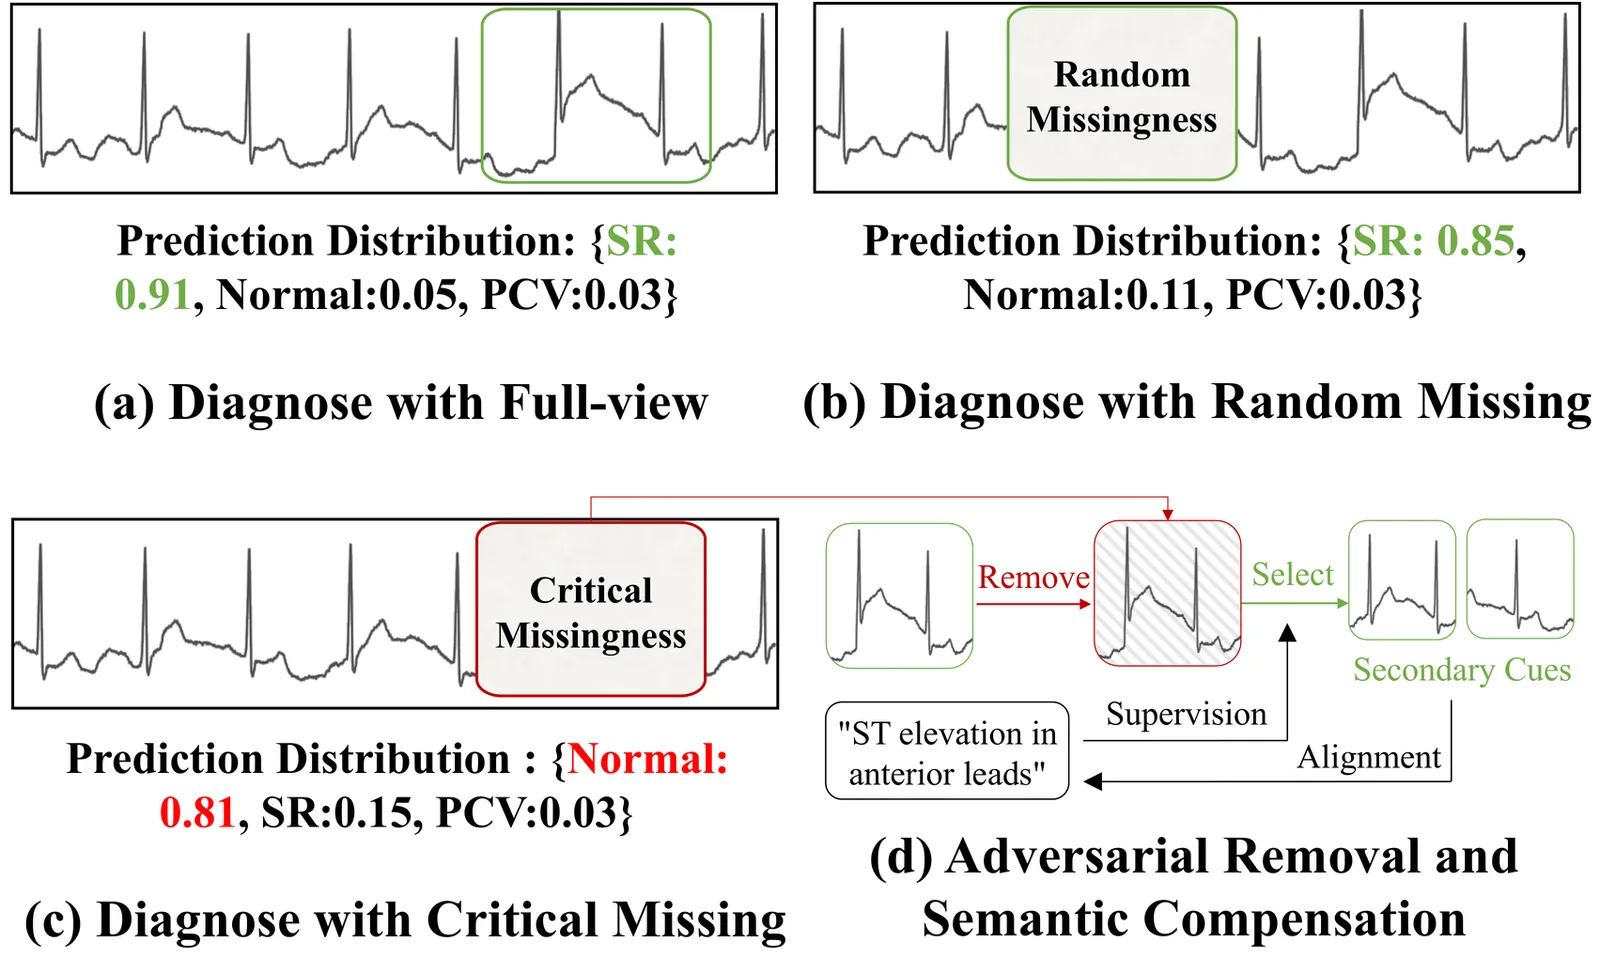
Semantic Compensation via Adversarial Removal for Robust Zero-Shot ECG Diagnosis
Recent ECG--language pretraining methods enable zero-shot diagnosis by aligning cardiac signals with clinical text, but they do not explicitly model robustness to partial observation and are typically studied under fully observed ECG settings. In practice, diagnostically critical leads or temporal segments may be missing due to electrode detachment, motion artifacts, or signal corruption, causing severe degradation of cross-modal semantic alignment. In this paper, we propose \textbf{SCAR}, a robust ECG--language pretraining framework for \textbf{S}emantic \textbf{C}ompensation via \textbf{A}dversarial \textbf{R}emoval. SCAR improves robustness by explicitly training the model to remain semantically aligned with semantically critical missingness and to recover diagnostic meaning from the remaining visible evidence. Specifically, we introduce a differentiable adversarial masker to remove the most alignment-critical spatio-temporal ECG tokens during training, forcing the ECG encoder to learn representations that remain semantically aligned with clinical text even when primary diagnostic evidence is missing. Under such adversarial corruption, we equip the ECG encoder with a semantically supervised adaptive selector that learns to reweight the remaining visible tokens and compensate with secondary yet diagnostically informative morphological cues. To evaluate robustness beyond classification accuracy, we further introduce Counterfactual Missingness Resolution Score (CMRS), which quantifies how well feature preserve diagnostic semantics under missingness. Experiments on $6$ datasets show that SCAR consistently improves semantic robustness under joint lead and temporal missingness, with particularly clear advantages in harder cases where primary diagnostic evidence is unavailable, while also yielding stronger linear-probing transferability.
2604.01498Apr 2026
View 2603.29736
Editing on the Generative Manifold: A Theoretical and Empirical Study of General Diffusion-Based Image Editing Trade-offs
Diffusion-based editing has rapidly evolved from curated inpainting tools into general-purpose editors spanning text-guided instruction following, mask-localized edits, drag-based geometric manipulation, exemplar transfer, and training-free composition systems. Despite strong empirical progress, the field lacks a unified treatment of core desiderata that govern practical usability: controllability (how precisely and continuously the user can specify an edit), faithfulness to user intent (semantic alignment to instructions), semantic consistency (preservation of identity and non-target content), locality (containment of changes), and perceptual quality (artifact suppression and detail retention). This paper provides a theoretical and empirical analysis of general diffusion-based image editing, connecting diverse paradigms through a common view of editing as guided transport on a learned image manifold. We first formalize editing as an operator induced by a conditional reverse-time generative process and define task-agnostic metrics capturing instruction adherence, region preservation, semantic consistency, and stability under repeated edits. We then develop theory describing edit dynamics under (i) noise-injection and denoising transport, (ii) inversion-and-edit pipelines and the propagation of inversion errors, and (iii) locality constraints implemented via masked guidance or hard constraints. Under mild Lipschitz assumptions on the learned score or flow field, we derive bounds connecting guidance strength and inversion error to measurable deviations in non-target regions, and we characterize accumulation effects under iterative multi-turn editing. Empirically, we benchmark representative paradigms.
2603.29736Mar 2026
View
Subjective Quality Assessment of Dynamic 3D Meshes in Virtual Reality Environment
A dynamic 3D mesh is a key component in Virtual Reality applications. However, this type of content demands a significant processing resource for real-time rendering. To reduce processing requirements while preserving the user experience, adjusting the level of detail of 3D meshes based on viewing distance has been proposed. In this paper, we conduct an extensive subjective quality evaluation to investigate the effects of the level of detail and viewing distance on user perception of dynamic 3D meshes in a VR environment. Our evaluation results in a subjective dataset containing user ratings of 320 test stimuli generated from eight dynamic 3D meshes. Result analysis shows that it is possible to remove half of a mesh's faces without causing noticeable degradation in user Quality of Experience (QoE). An evaluation of popular objective quality metrics reveals that both 2D-based and 3D-based metrics have low correlation with subjective scores. Based on the subjective dataset, we develop a novel QoE prediction model that can accurately predict the MOS of a dynamic 3D mesh at a given level of detail and viewing distance. In addition, a QoE-aware resource allocation framework is proposed and evaluated under different resource constraints, showing significant improvement in the total QoE compared to conventional methods.
2603.29166Mar 2026
View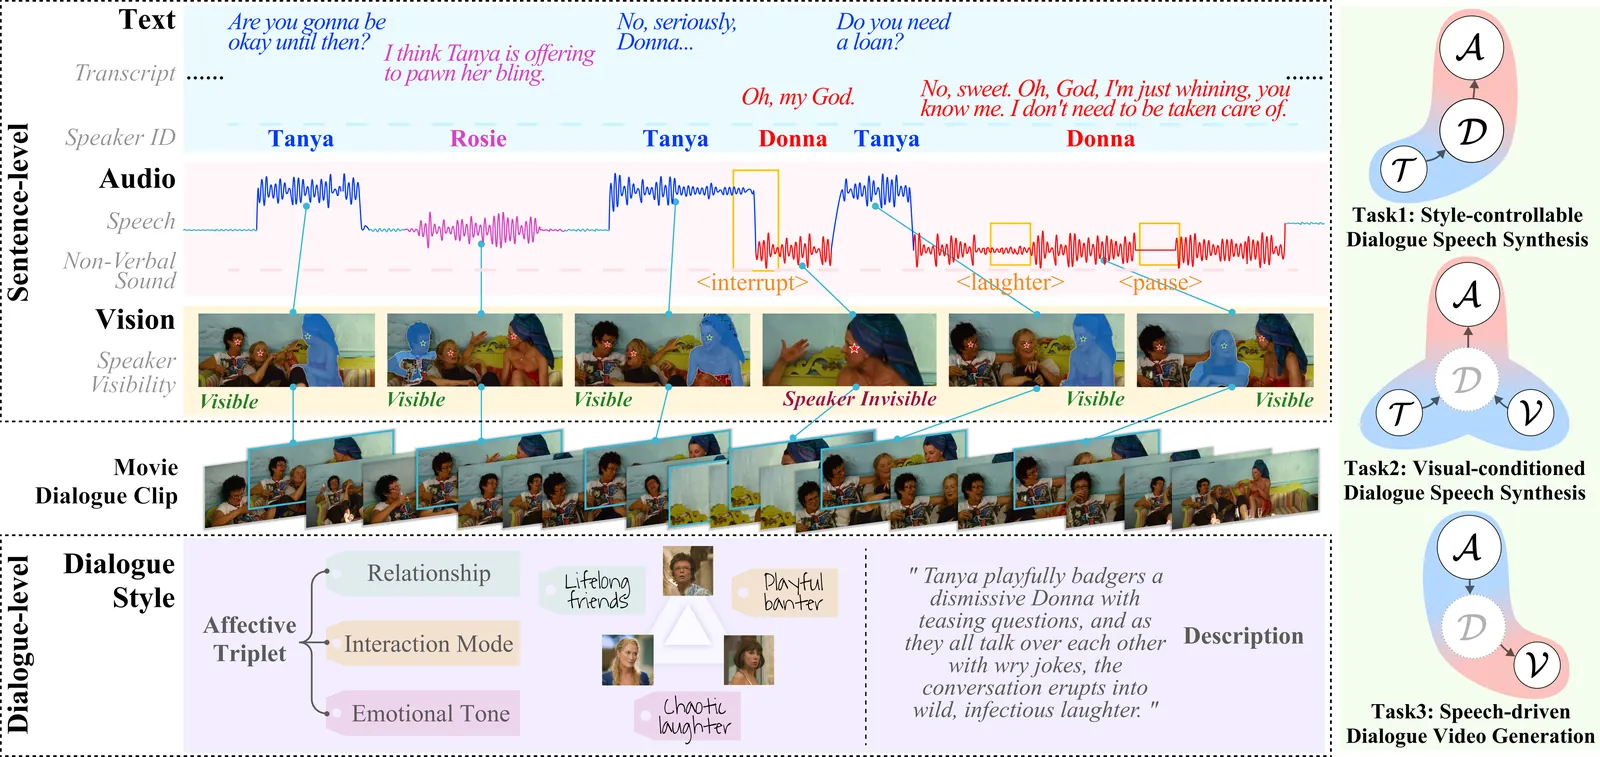
From Natural Alignment to Conditional Controllability in Multimodal Dialogue
The recent advancement of Artificial Intelligence Generated Content (AIGC) has led to significant strides in modeling human interaction, particularly in the context of multimodal dialogue. While current methods impressively generate realistic dialogue in isolated modalities like speech or vision, challenges remain in controllable Multimodal Dialogue Generation (MDG). This paper focuses on the natural alignment between speech, vision, and text in human interaction, aiming for expressive dialogue generation through multimodal conditional control. To address the insufficient richness and diversity of dialogue expressiveness in existing datasets, we introduce a novel multimodal dialogue annotation pipeline to curate dialogues from movies and TV series with fine-grained annotations in interactional characteristics. The resulting MM-Dia dataset (360+ hours, 54,700 dialogues) facilitates explicitly controlled MDG, specifically through style-controllable dialogue speech synthesis. In parallel, MM-Dia-Bench (309 highly expressive dialogues with visible single-/dual-speaker scenes) serves as a rigorous testbed for implicit cross-modal MDG control, evaluating audio-visual style consistency across modalities. Extensive experiments demonstrate that training on MM-Dia significantly enhances fine-grained controllability, while evaluations on MM-Dia-Bench reveal limitations in current frameworks to replicate the nuanced expressiveness of human interaction. These findings provides new insights and challenges for multimodal conditional dialogue generation.
2603.29162Mar 2026
View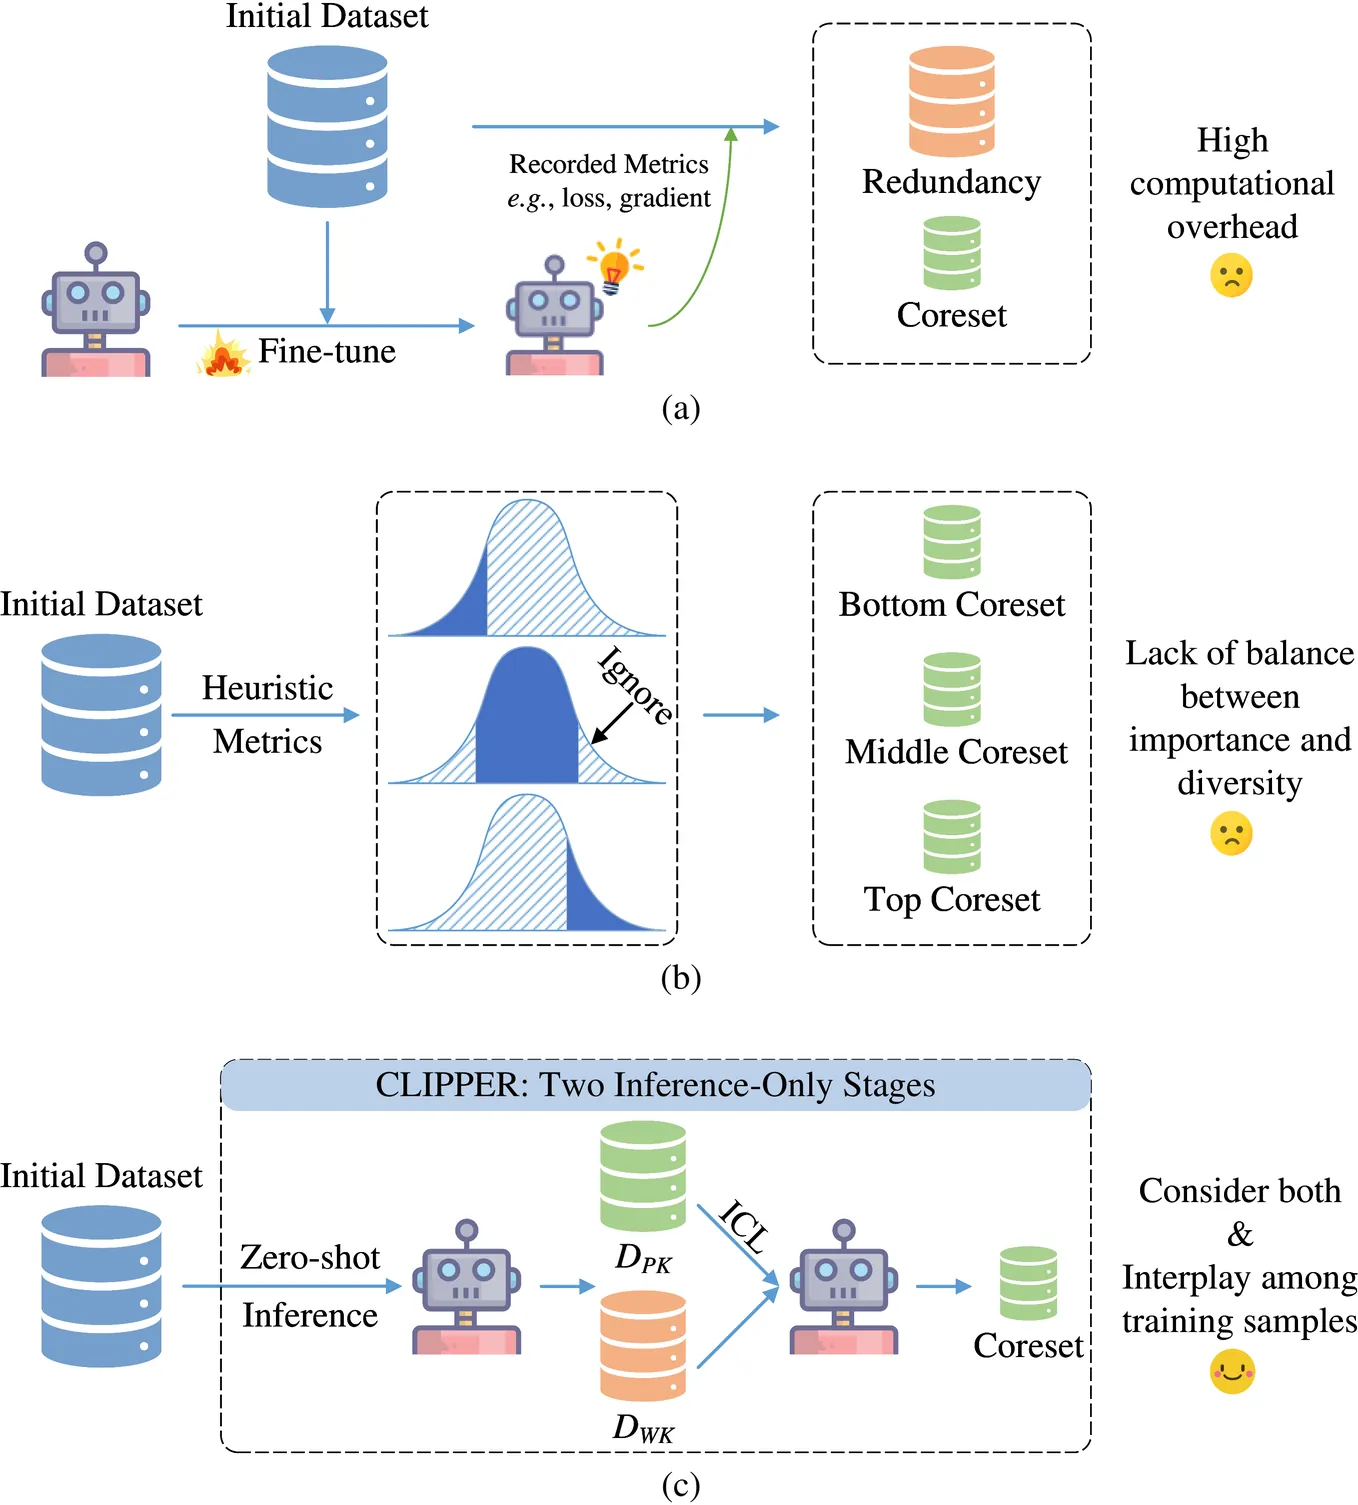
Is One-Shot In-Context Learning Helpful for Data Selection in Task-Specific Fine-Tuning of Multimodal LLMs?
Injecting world knowledge into pretrained multimodal large language models (MLLMs) is essential for domain-specific applications. Task-specific fine-tuning achieves this by tailoring MLLMs to high-quality in-domain data but encounters scalability challenges as datasets grow, necessitating a trade-off between performance and computational overhead. Existing data selection methods rely on additional scoring models or heuristic clustering, failing to concentrate on both data importance and diversity. Moreover, both methods overlook the interplay among training samples. To address these limitations, we propose CLIPPER, a training-free data selection pipeline that separates parameter and world knowledge, and leverages in-context learning to probe model responses to different demonstration-query combinations. CLIPPER identifies coresets that mirror the original dataset's perplexity distribution, preserving critical samples while maintaining diversity. Experiments on two MLLMs and three datasets show that CLIPPER matches full fine-tuning performance with significantly lower costs: Qwen2.5-VL-7B attains 47% data efficiency on VRSBench, and Llama-3.2-11B-Vision-Instruct reduces ScienceQA training time by 37%.
2603.28058Mar 2026
View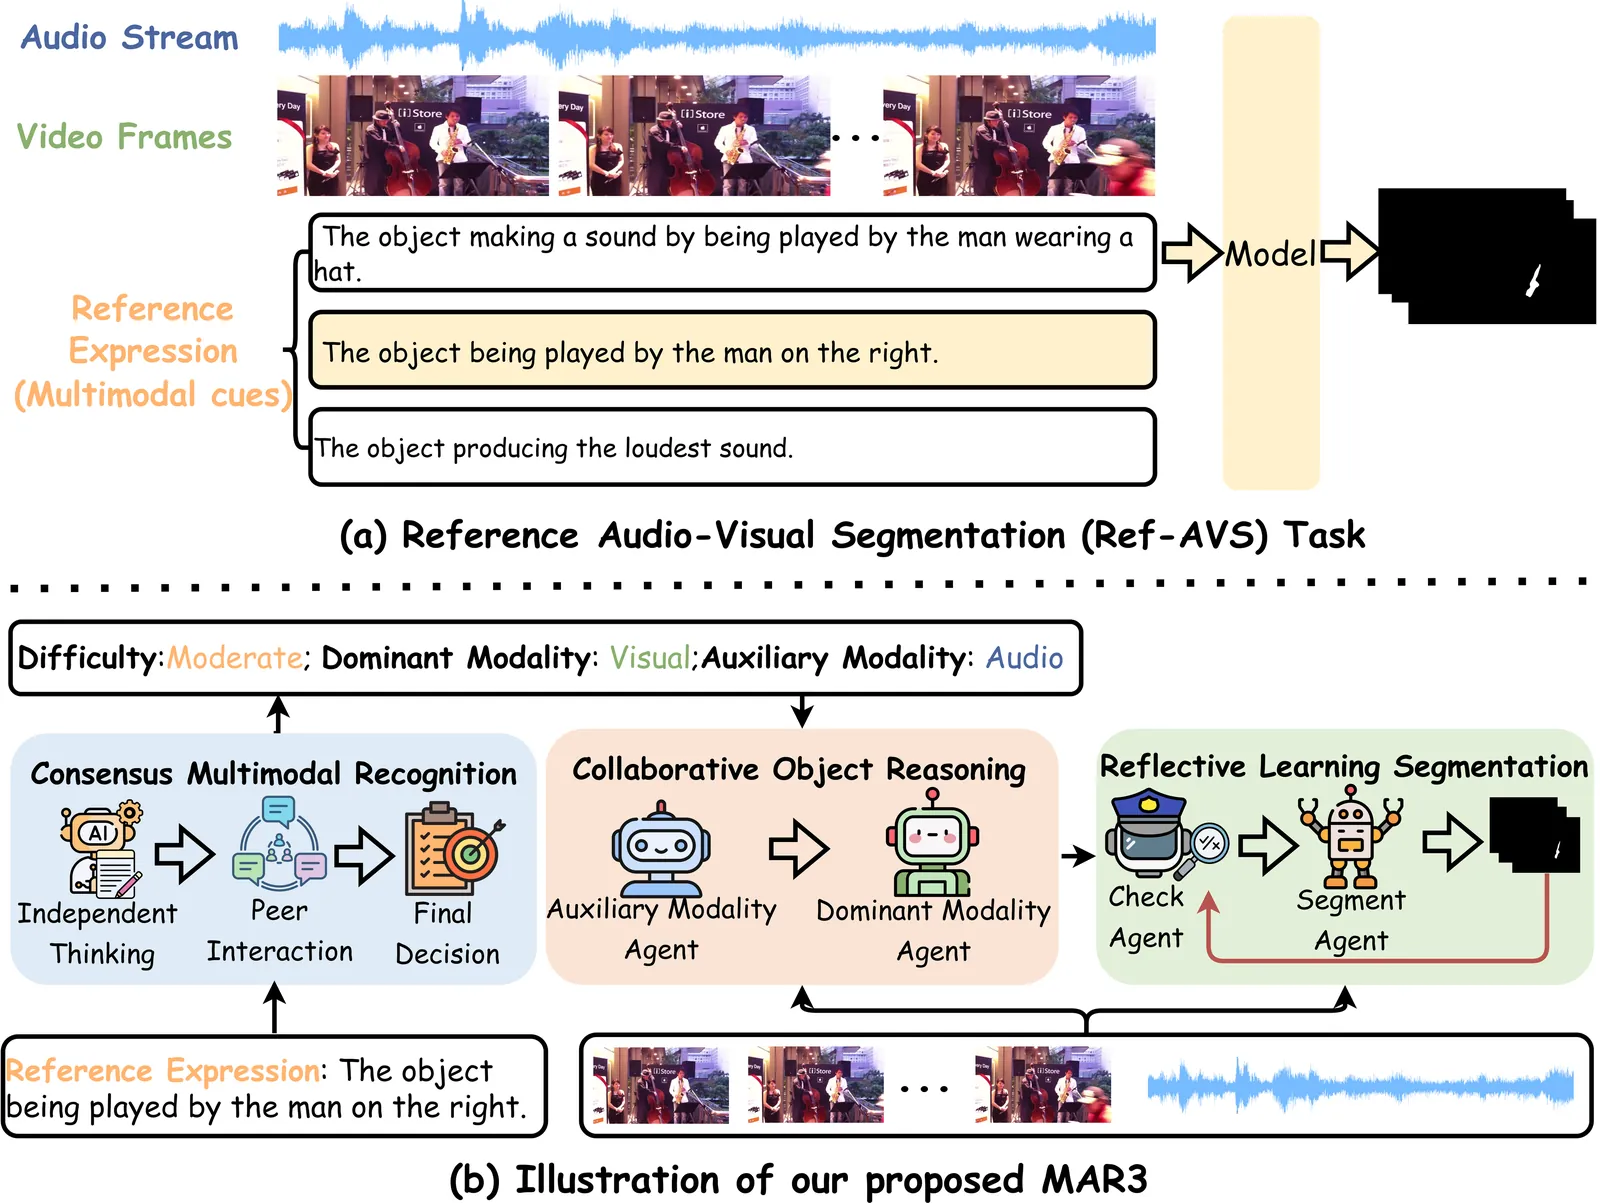
MAR3: Multi-Agent Recognition, Reasoning, and Reflection for Reference Audio-Visual Segmentation
Reference Audio-Visual Segmentation (Ref-AVS) aims to segment objects in audible videos based on multimodal cues in reference expressions. Previous methods overlook the explicit recognition of expression difficulty and dominant modality in multimodal cues, over-rely on the quality of the instruction-tuning dataset for object reasoning, and lack reflective validation of segmentation results, leading to erroneous mask predictions. To address these issues, in this paper, we propose a novel training-free Multi-Agent Recognition, Reasoning, and Reflection framework to achieve high-quality Reference Audio-Visual Segmentation, termed MAR3. Incorporating the sociological Delphi theory to achieve robust analysis, a Consensus Multimodal Recognition mechanism is proposed that enables LLM agents to explicitly recognize the difficulty of reference expressions and the dominant modality of multimodal cues. Based on our modality-dominant difficulty rule, we propose an adaptive Collaborative Object Reasoning strategy to reliably reason about the referred object. To further ensure precise mask prediction, we develop a Reflective Learning Segmentation mechanism, in which a check agent examines intermediate segmentation results and iteratively corrects the object text prompt of the segment agent. Experiments demonstrate that MAR3 achieves superior performance (69.2% in J&F) on the Ref-AVSBench dataset, outperforming SOTA by 3.4% absolutely.
2603.27706Mar 2026
View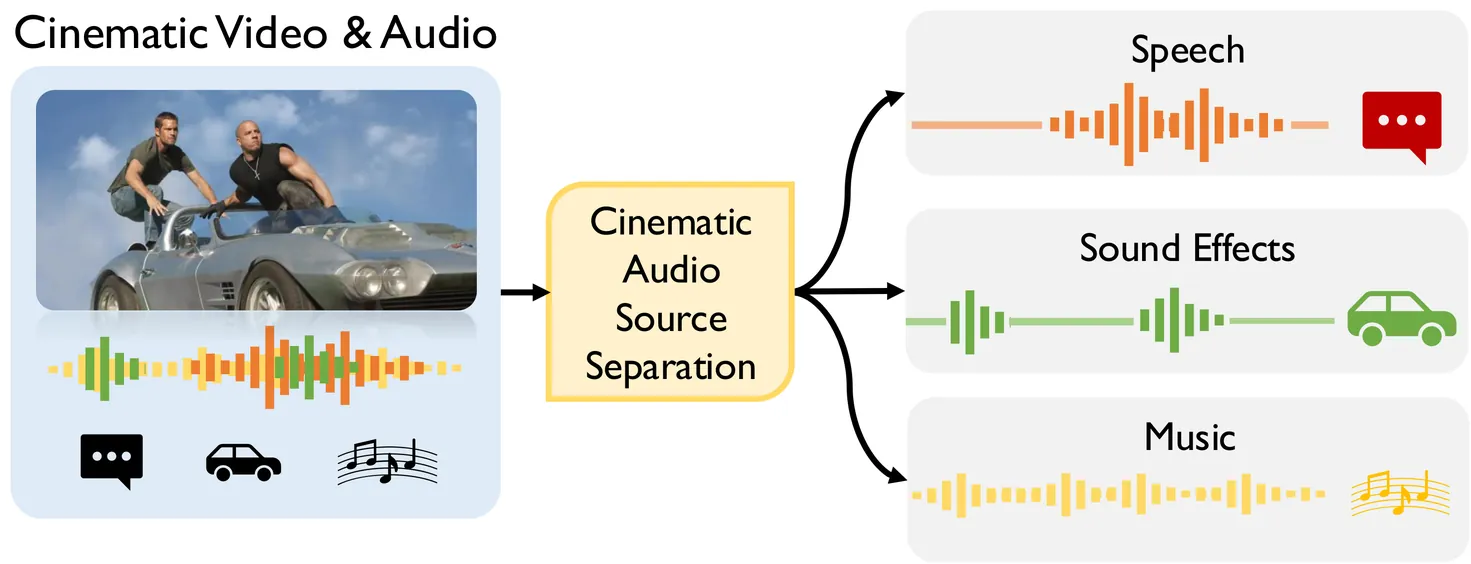
Cinematic Audio Source Separation Using Visual Cues
Cinematic Audio Source Separation (CASS) aims to decompose mixed film audio into speech, music, and sound effects, enabling applications like dubbing and remastering. Existing CASS approaches are audio-only, overlooking the inherent audio-visual nature of films, where sounds often align with visual cues. We present the first framework for audio-visual CASS (AV-CASS), leveraging visual context to enhance separation quality. Our method formulates CASS as a conditional generative modeling problem using conditional flow matching, enabling multimodal audio source separation. To address the lack of cinematic datasets with isolated sound tracks, we introduce a training data synthesis pipeline that pairs in-the-wild audio and video streams (e.g., facial videos for speech, scene videos for effects) and design a dedicated visual encoder for this dual-stream setup. Trained entirely on synthetic data, our model generalizes effectively to real-world cinematic content and achieves strong performance on synthetic, real-world, and audio-only CASS benchmarks. Code and demo are available at \url{https://cass-flowmatching.github.io}.
2603.26113Mar 2026
View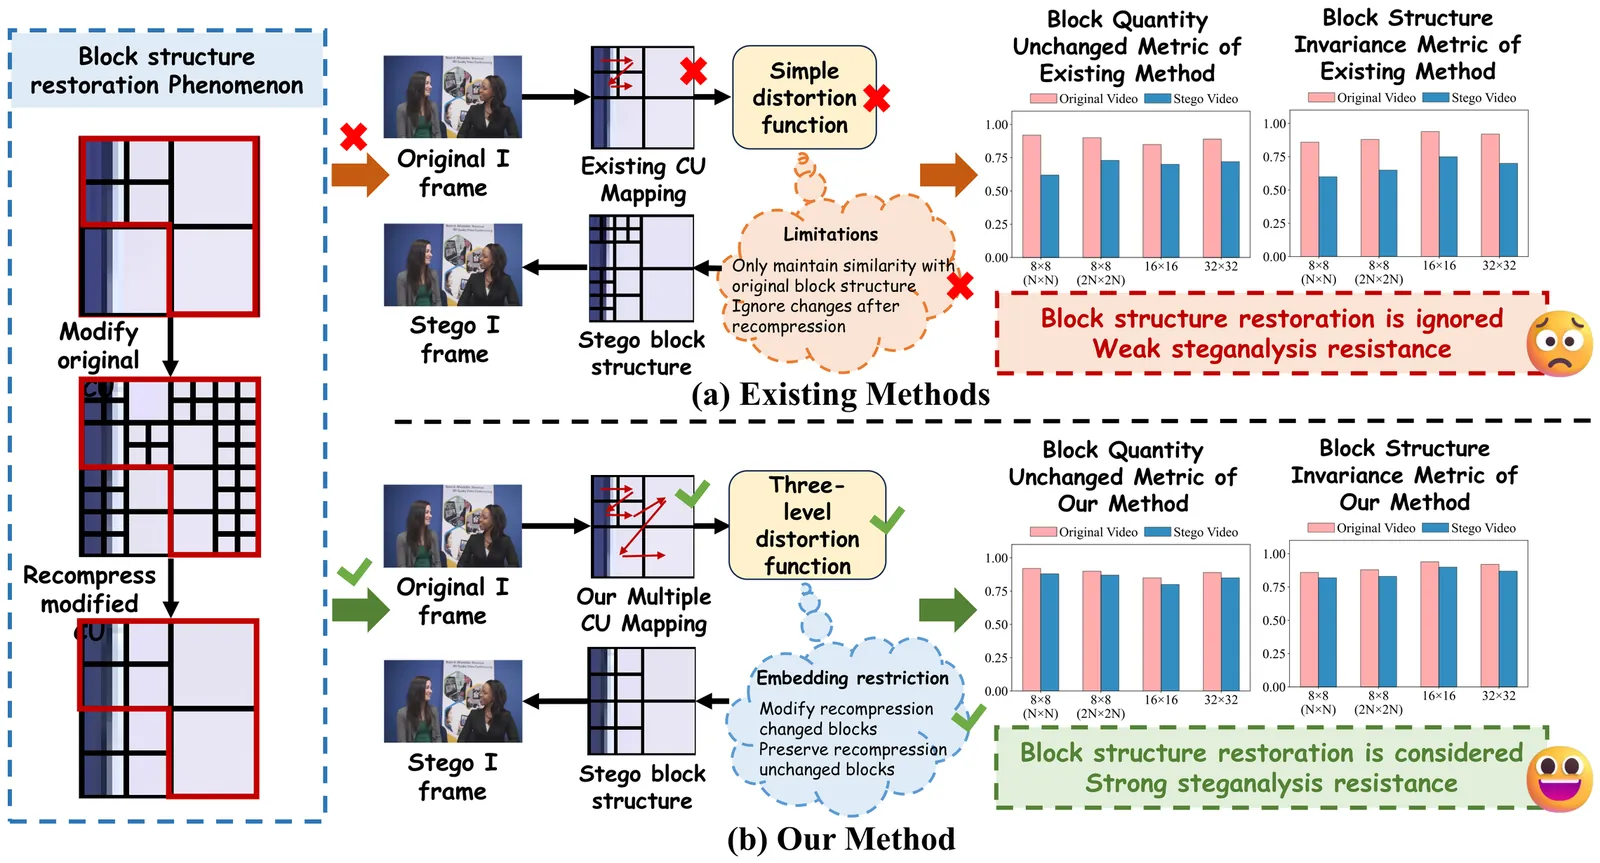
A Video Steganography for H.265/HEVC Based on Multiple CU Size and Block Structure Distortion
Video steganography based on block structure, which embeds secret information by modifying Coding Unit (CU) block structure of I-frames, is currently a research hotspot. However, the existing algorithms still suffer from the limitation of poor anti-steganalysis, which results from significantly disrupting the original CU block structure after embedding secret information. To overcome this limitation, this paper proposes a video steganography algorithm based on multiple CU size and block structure distortion. Our algorithm introduces three key innovations: 1) a CU Block Structure Stability Metric (CBSSM) based on CU block structure restoration phenomenon to reveal the reasons for the insufficient anti-steganalysis performance of current algorithms. 2) a novel mapping rule based on multiple CU size to reduce block structure change and enhance embedding capacity. 3) a three-level distortion function based on block structure to better guide the secret information embedding. This triple strategy ensures that the secret information embedding minimizes disruption to the original CU block structure while concealing it primarily in areas where block structure changes occur after recompression, ultimately enhancing the algorithm's anti-steganalysis. Comprehensive experimental results highlight the crucial role of the proposed CBSSM in evaluating anti-steganalysis performance even at a low embedding rate. Meanwhile, compared to State-of-the-Art video steganography algorithms based on block structure, our proposed steganography algorithm exhibits greater anti-steganalysis, as well as further improving visual quality, bitrate increase ratio and embedding capacity.
2603.22850Mar 2026
View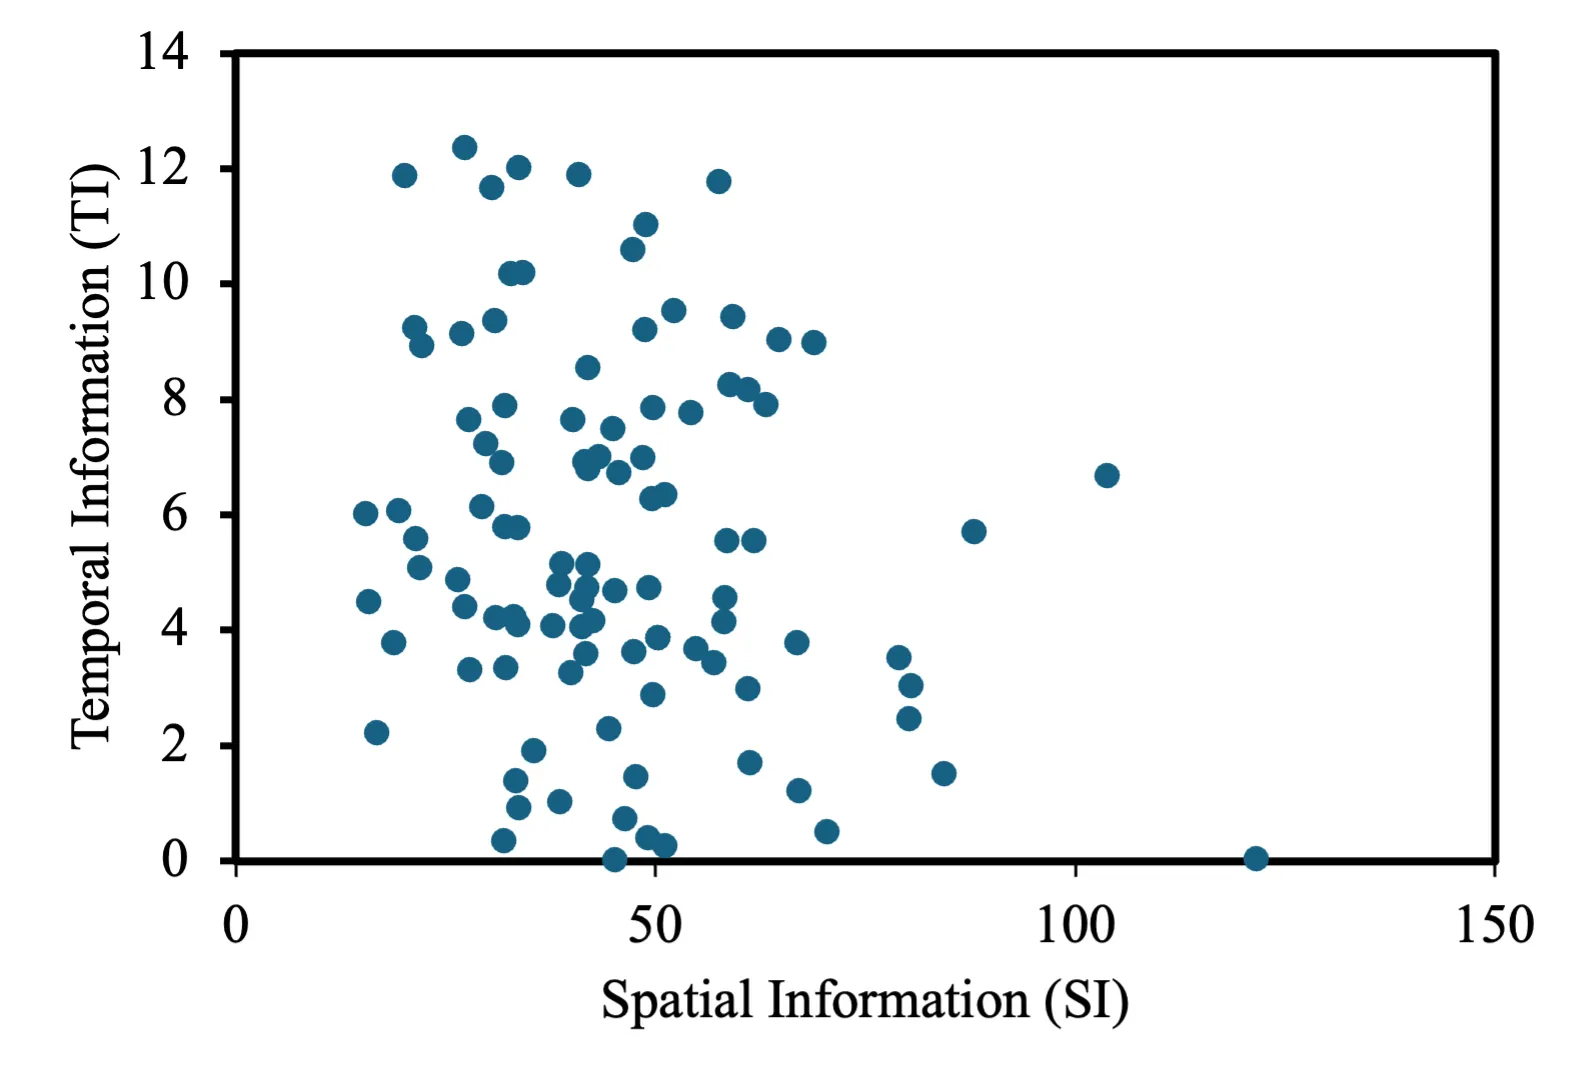
Short-Form Video Viewing Behavior Analysis and Multi-Step Viewing Time Prediction
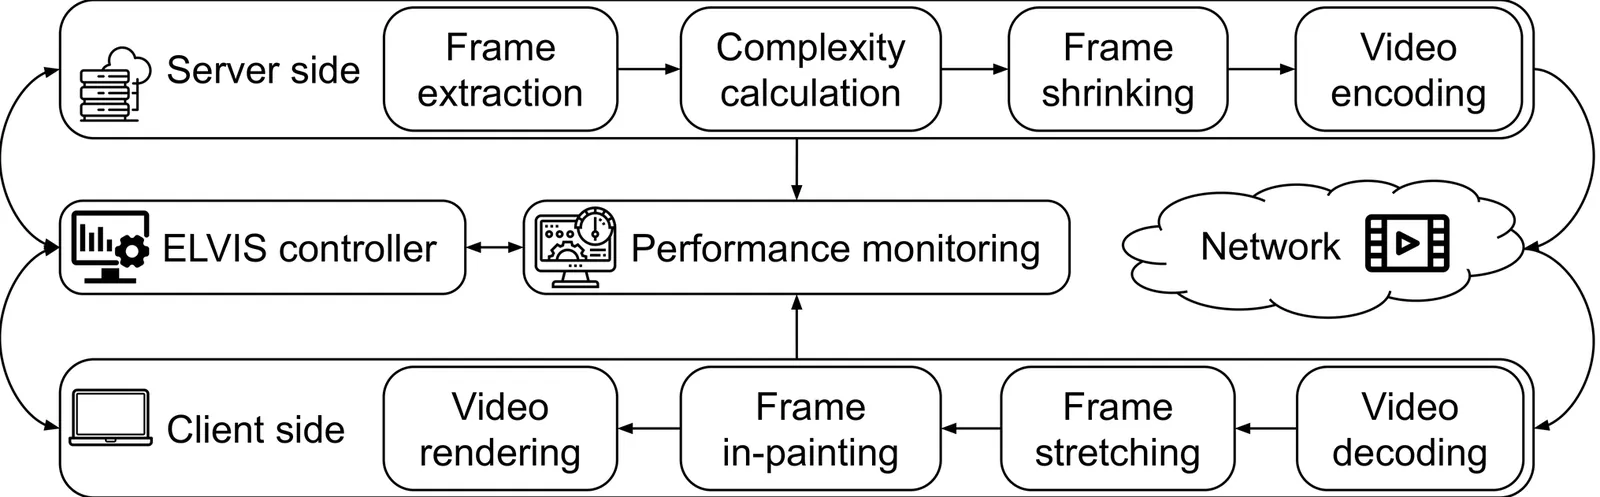
Short-form videos have become one of the most popular user-generated content formats nowadays. Popular short-video platforms use a simple streaming approach that preloads one or more videos in the recommendation list in advance. However, this approach results in significant data wastage, as a large portion of the downloaded video data is not used due to the user's early skip behavior. To address this problem, the chunk-based preloading approach has been proposed, where videos are divided into chunks, and preloading is performed in a chunk-based manner to reduce data wastage. To optimize chunk-based preloading, it is important to understand the user's viewing behavior in short-form video streaming. In this paper, we conduct a measurement study to construct a user behavior dataset that contains users' viewing times of one hundred short videos of various categories. Using the dataset, we evaluate the performance of standard time-series forecasting algorithms for predicting user viewing time in short-form video streaming. Our evaluation results show that Auto-ARIMA generally achieves the lowest and most stable forecasting errors across most experimental settings. The remaining methods, including AR, LR, SVR, and DTR, tend to produce higher errors and exhibit lower stability in many cases. The dataset is made publicly available at https://nvduc.github.io/shortvideodataset.
2603.22663Mar 2026
View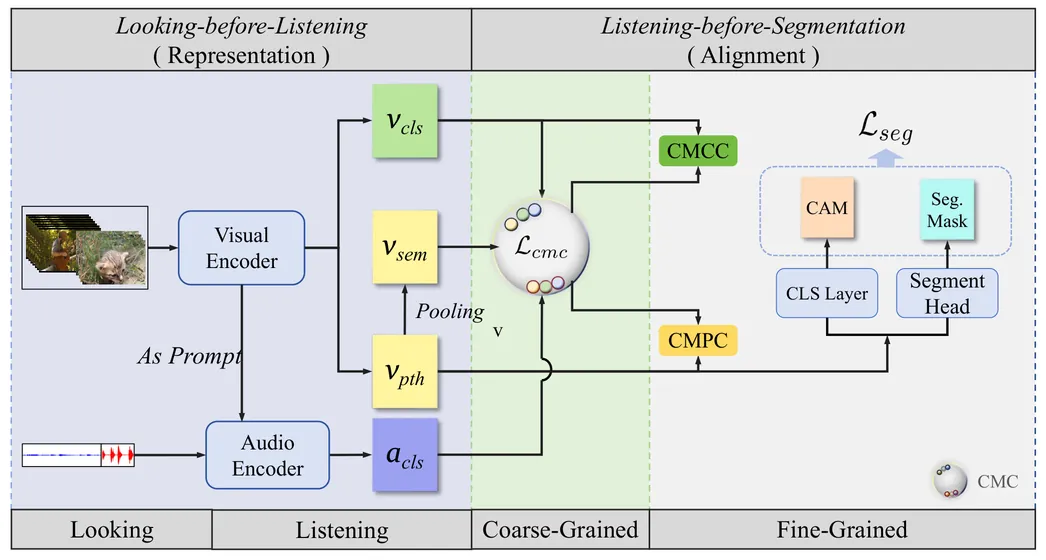
Look, Listen and Segment: Towards Weakly Supervised Audio-visual Semantic Segmentation
Audio-Visual Semantic Segmentation (AVSS) aligns audio and video at the pixel level but requires costly per-frame annotations. We introduce Weakly Supervised Audio-Visual Semantic Segmentation (WSAVSS), which uses only video-level labels to generate per-frame semantic masks of sounding objects. We decompose WSAVSS into looking, listening, and segmentation, and propose Progressive Cross-modal Alignment for Semantics (PCAS) with two modules: *Looking-before-Listening* and *Listening-before-Segmentation*. PCAS builds a classification task to train the audio-visual encoder using video labels, injects visual semantic prompts to enhance frame-level audio understanding, and then applies progressive contrastive alignment to map audio categories to image regions without mask annotations. Experiments show PCAS achieves state-of-the-art performance among weakly supervised methods on AVS and remains competitive with fully supervised baselines on AVSS, validating its effectiveness.
2603.21948Mar 2026
View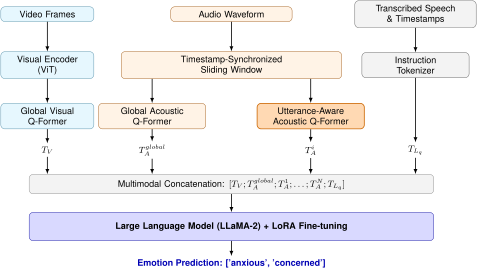
AcoustEmo: Open-Vocabulary Emotion Reasoning via Utterance-Aware Acoustic Q-Former
Multimodal Large Language Models (MLLMs) excel in Open-Vocabulary (OV) emotion recognition but often neglect fine-grained acoustic modeling. Existing methods typically use global audio encoders, failing to capture subtle, local temporal dynamics like micro-prosody and intonation shifts within individual utterances. To address this, we propose AcoustEmo, a time-sensitive MLLM featuring a novel Utterance-Aware Acoustic Q-Former. Our approach utilizes a timestamp-synchronized sliding window to dynamically extract segment-level audio tokens instead of coarse global representations. This enables the model to explicitly trace the temporal evolution of subtle acoustic clues and capture deep contextual dependencies in dialogues. Experiments on the Explainable Multimodal Emotion Recognition (EMER) task show that AcoustEmo significantly enhances complex emotion reasoning, outperforming baselines while maintaining robust contextual accuracy.
2603.20894Mar 2026
View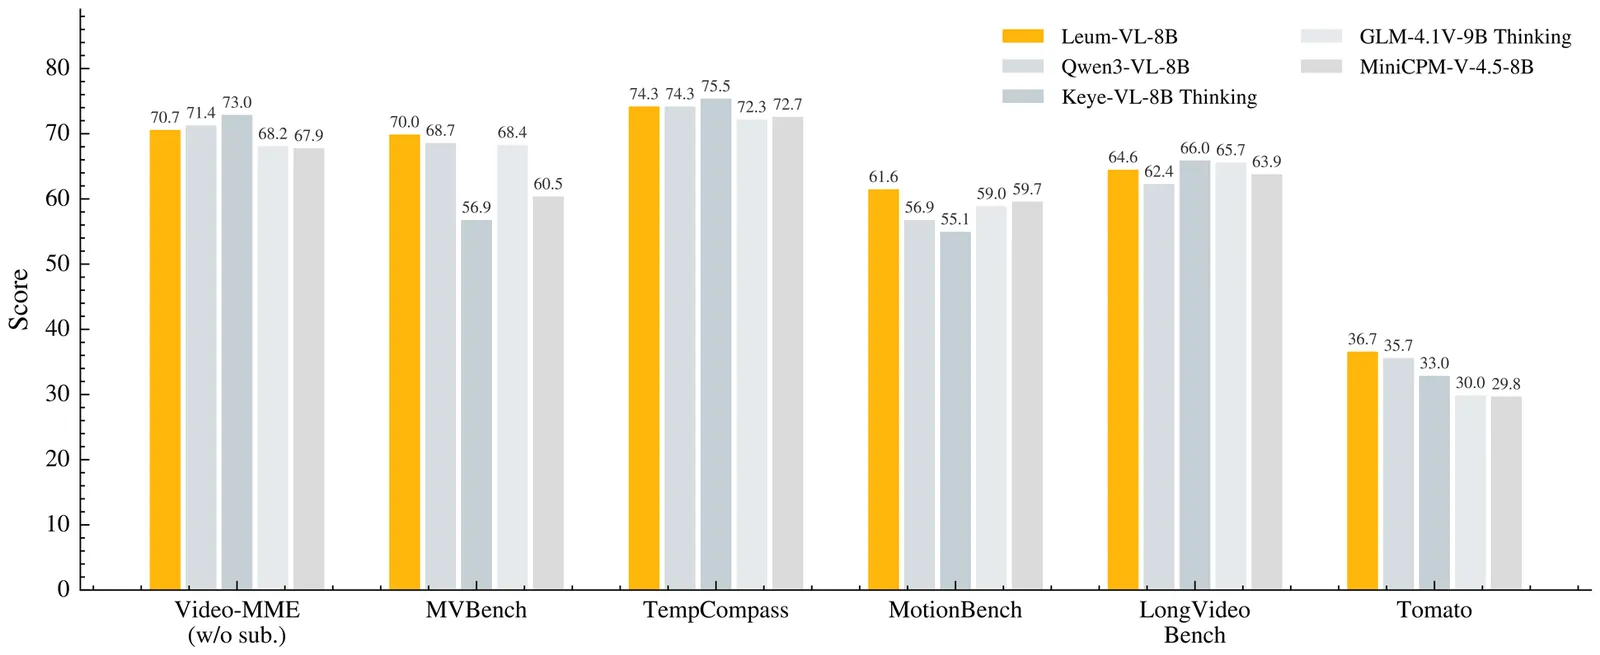
Leum-VL Technical Report
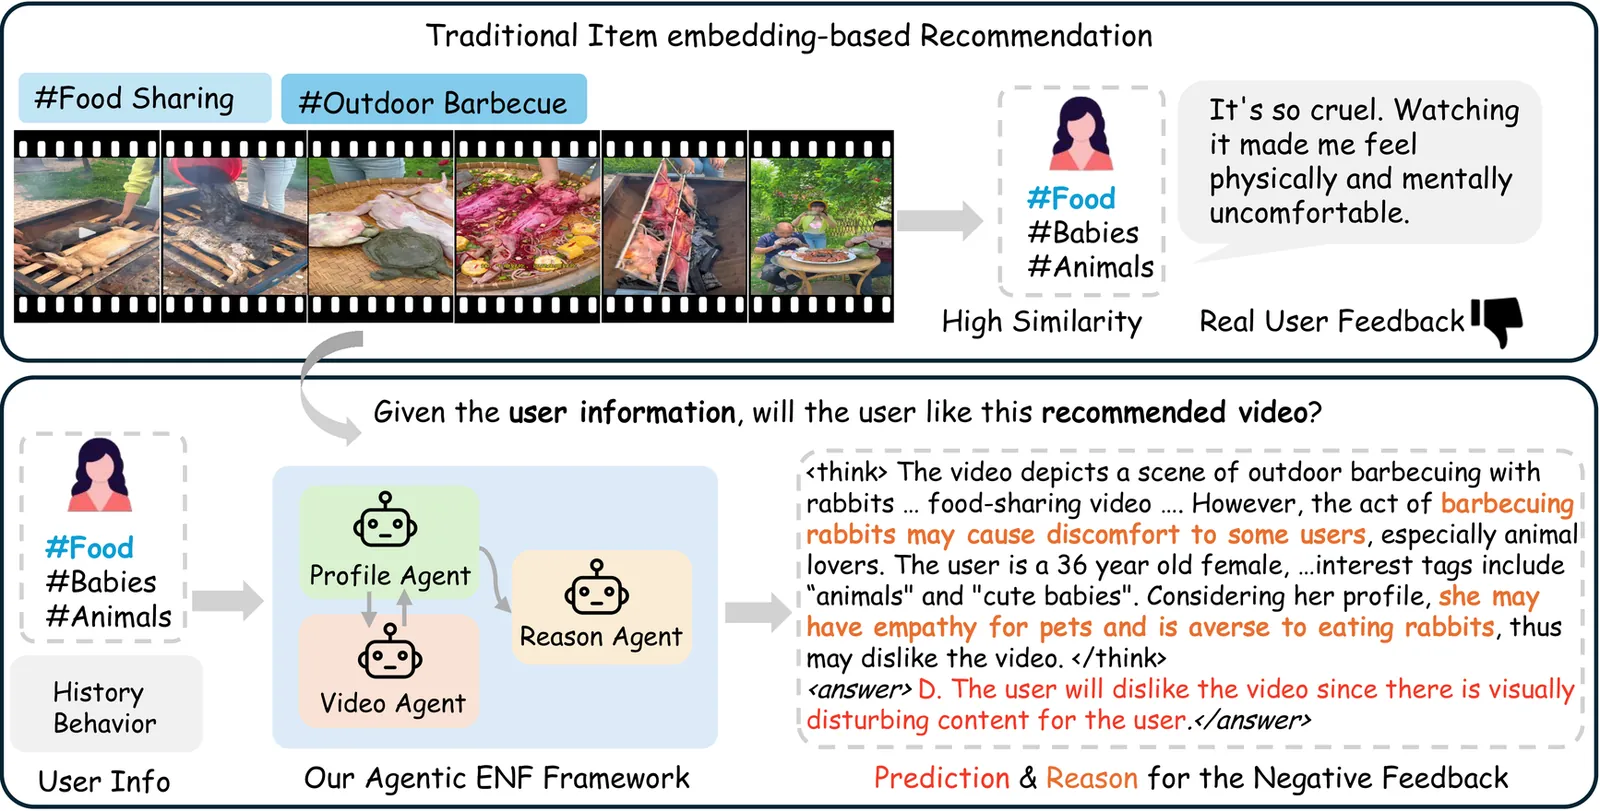
A short video succeeds not simply because of what it shows, but because of how it schedules attention -- yet current multimodal models lack the structural grammar to parse or produce this organization. Existing models can describe scenes, answer event-centric questions, and read on-screen text, but they are far less reliable at identifying timeline-grounded units such as hooks, cut rationales, shot-induced tension, and platform-facing packaging cues. We propose SV6D (Structured Video in Six Dimensions), inspired by professional storyboard practice in film and television production, a representation framework that decomposes internet-native video into six complementary structural dimensions -- subject, aesthetics, camera language, editing, narrative, and dissemination -- with each label tied to physically observable evidence on the timeline. We formalize a unified optimization objective over SV6D that combines Hungarian-matched temporal alignment, dimension-wise semantic label distance, and quality regularization. Building on this framework, we present Leum-VL-8B, an 8B video-language model that realizes the SV6D objective through an expert-driven post-training pipeline, further refined through verifiable reinforcement learning on perception-oriented tasks. Leum-VL-8B achieves 70.8 on VideoMME (w/o subtitles), 70.0 on MVBench, and 61.6 on MotionBench, while remaining competitive on general multimodal evaluations such as MMBench-EN. We also construct FeedBench, a benchmark for structure-sensitive short-video understanding. Our results indicate that the missing layer in video AI is not pixel generation but structural representation: grounded on the timeline, linked to visible evidence, and directly consumable by downstream workflows such as editing, retrieval, recommendation, and generation control, including text-heavy internet video formats with overlays and image-text layouts.
2603.20354Mar 2026
View
Modeling the Impacts of Swipe Delay on User Quality of Experience in Short Video Streaming
Short video streaming platforms have gained immense popularity in recent years, transforming the way users consume video content. A critical aspect of user interaction with these platforms is the swipe gesture, which allows users to navigate through videos seamlessly. However, the delay between a user's swipe action and the subsequent video playback can significantly impact the overall user experience. This paper presents the first systematic study investigating the effects of swipe delay on user Quality of Experience (QoE) in short video streaming. In particular, we conduct a subjective quality assessment containing 132 swipe delay patterns. The obtained results show that user experience is affected not only by the swipe delay duration, but also by the number of delays and their temporal positions. A single delay of eight seconds or longer is likely to lead to user dissatisfaction. Moreover, early-session delays are less harmful to user QoE than late-session delays. Based on the findings, we propose a novel QoE model that accurately predicts user experience based on swipe delay characteristics. The proposed model demonstrates high correlation with subjective ratings, outperforming existing models in short video streaming.
2603.18575Mar 2026
View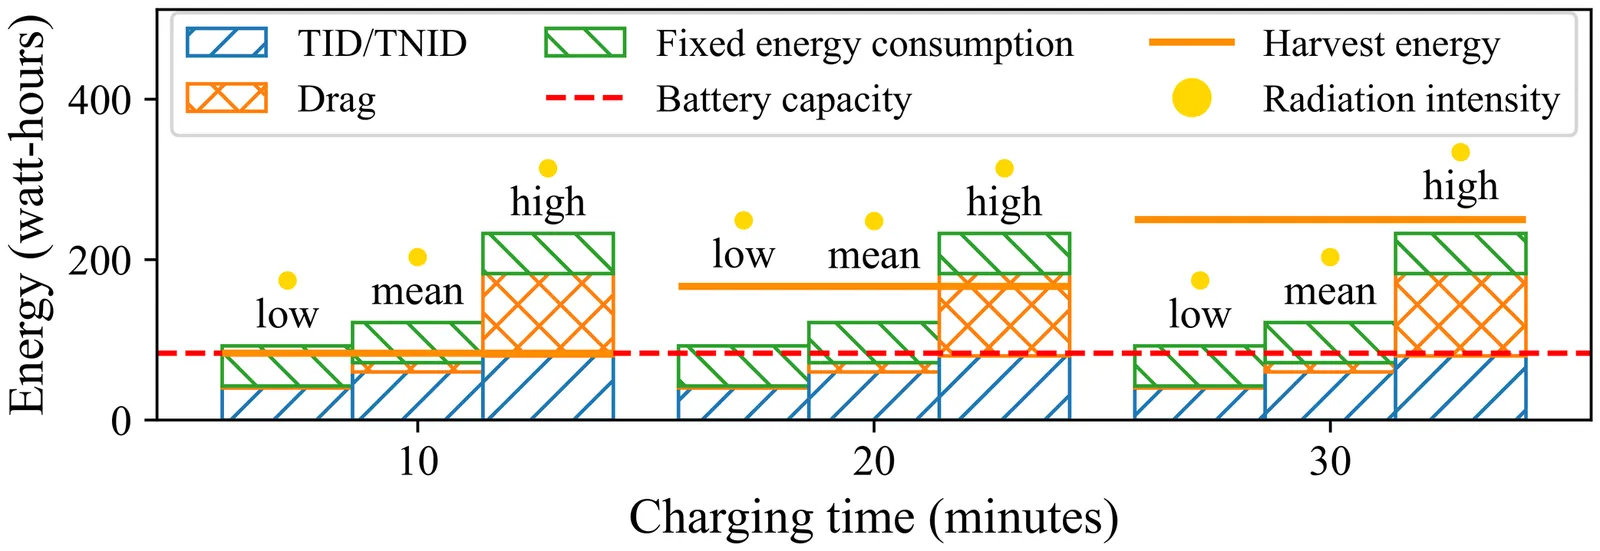
Rethink Web Service Resilience in Space: A Radiation-Aware and Sustainable Transmission Solution
Low Earth Orbit (LEO) satellite networks such as Starlink and Project Kuiper are increasingly integrated with cloud infrastructures, forming an important internet backbone for global web services. By extending connectivity to remote regions, oceans, and disaster zones, these networks enable reliable access to applications ranging from real-time WebRTC communication to emergency response portals. Yet the resilience of these web services is threatened by space radiation: it degrades hardware, drains batteries, and disrupts continuity, even if the space-cloud integrated providers use machine learning to analyze space weather and radiation data. Specifically, conventional fixes like altitude adjustments and thermal annealing consume energy; neglecting this energy use results in deep discharge and faster battery aging, whereas sleep modes risk abrupt web session interruptions. Efficient network-layer mitigation remains a critical gap. We propose RALT (Radiation-Aware LEO Transmission), a control-plane solution that dynamically reroutes traffic during radiation events, accounting for energy constraints to minimize battery degradation and sustain service performance. Our work shows that unlocking space-based web services' full potential for global reliable connectivity requires rethinking resilience through the lens of the space environment itself.
2603.18526Mar 2026
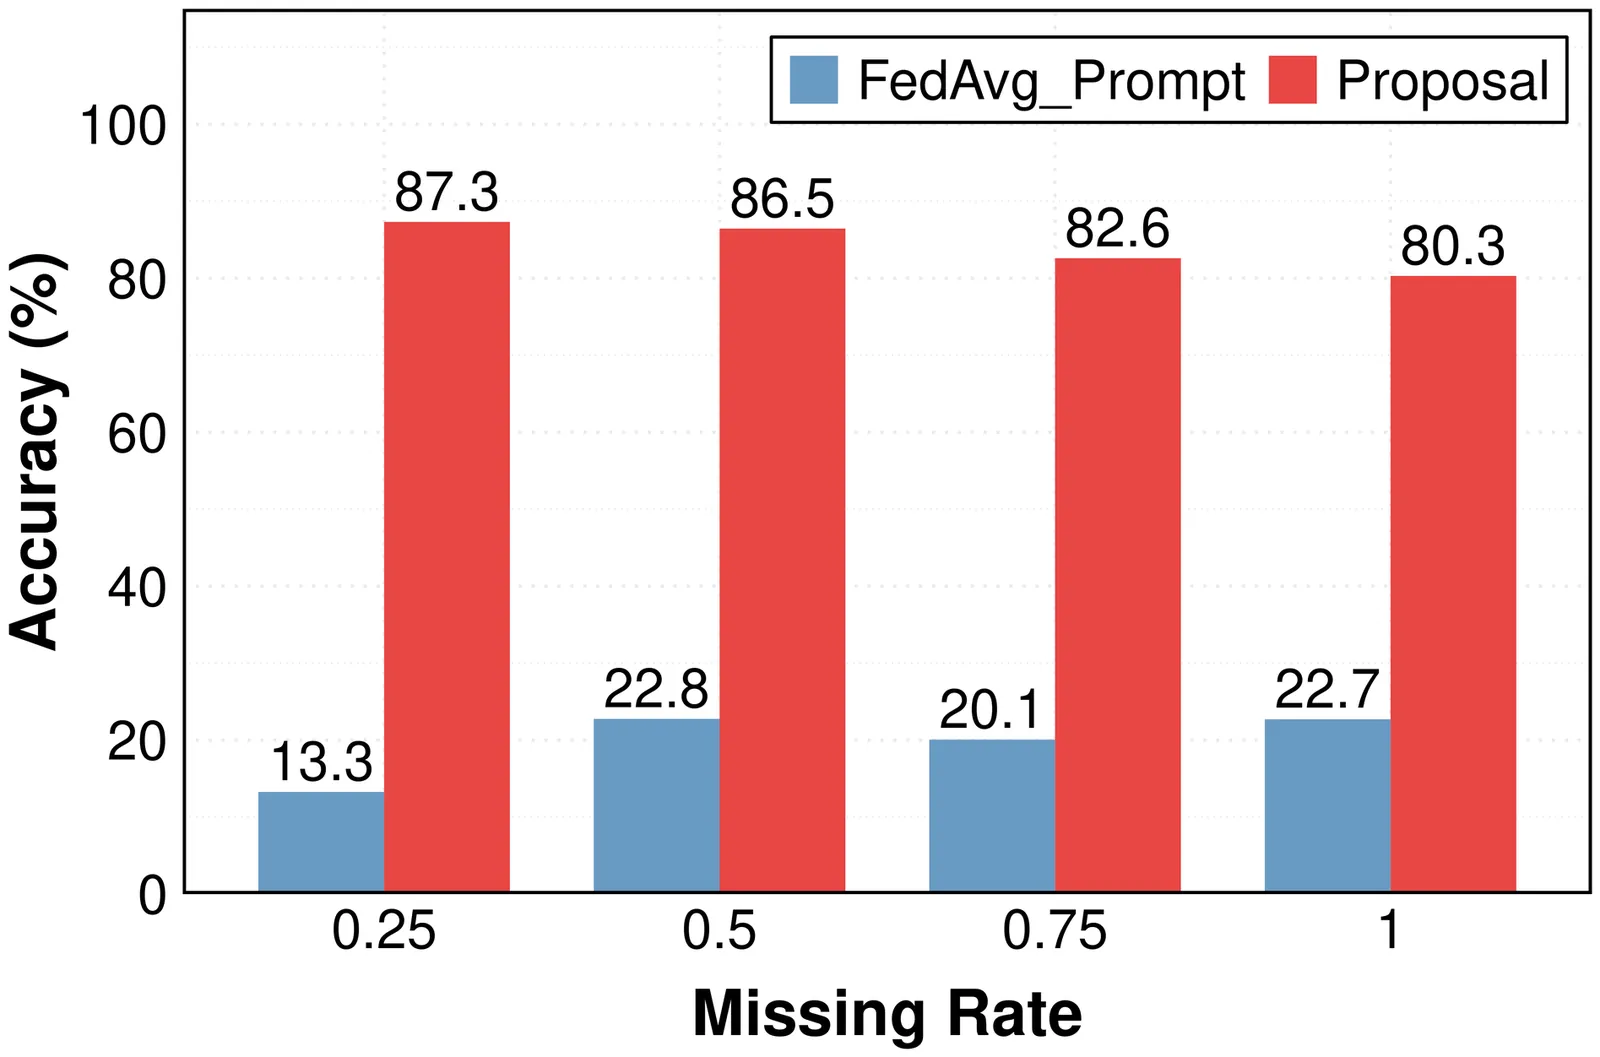
View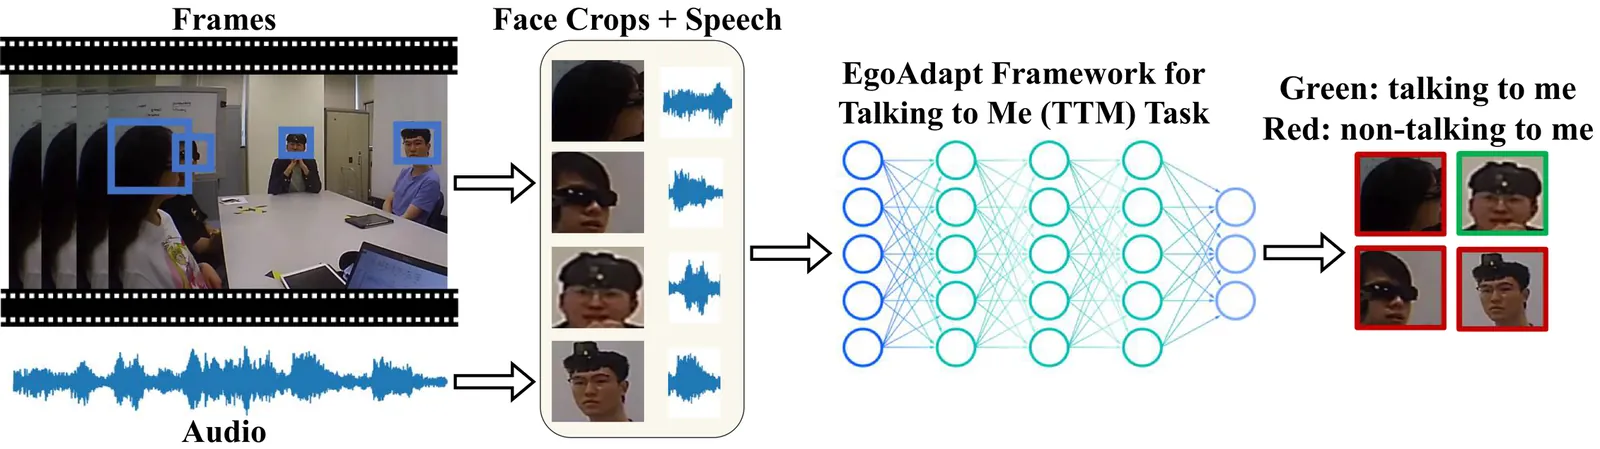
EgoAdapt: Enhancing Robustness in Egocentric Interactive Speaker Detection Under Missing Modalities
TTM (Talking to Me) task is a pivotal component in understanding human social interactions, aiming to determine who is engaged in conversation with the camera-wearer. Traditional models often face challenges in real-world scenarios due to missing visual data, neglecting the role of head orientation, and background noise. This study addresses these limitations by introducing EgoAdapt, an adaptive framework designed for robust egocentric "Talking to Me" speaker detection under missing modalities. Specifically, EgoAdapt incorporates three key modules: (1) a Visual Speaker Target Recognition (VSTR) module that captures head orientation as a non-verbal cue and lip movement as a verbal cue, allowing a comprehensive interpretation of both verbal and non-verbal signals to address TTM, setting it apart from tasks focused solely on detecting speaking status; (2) a Parallel Shared-weight Audio (PSA) encoder for enhanced audio feature extraction in noisy environments; and (3) a Visual Modality Missing Awareness (VMMA) module that estimates the presence or absence of each modality at each frame to adjust the system response dynamically.Comprehensive evaluations on the TTM benchmark of the Ego4D dataset demonstrate that EgoAdapt achieves a mean Average Precision (mAP) of 67.39% and an Accuracy (Acc) of 62.01%, significantly outperforming the state-of-the-art method by 4.96% in Accuracy and 1.56% in mAP.
2603.18082Mar 2026
View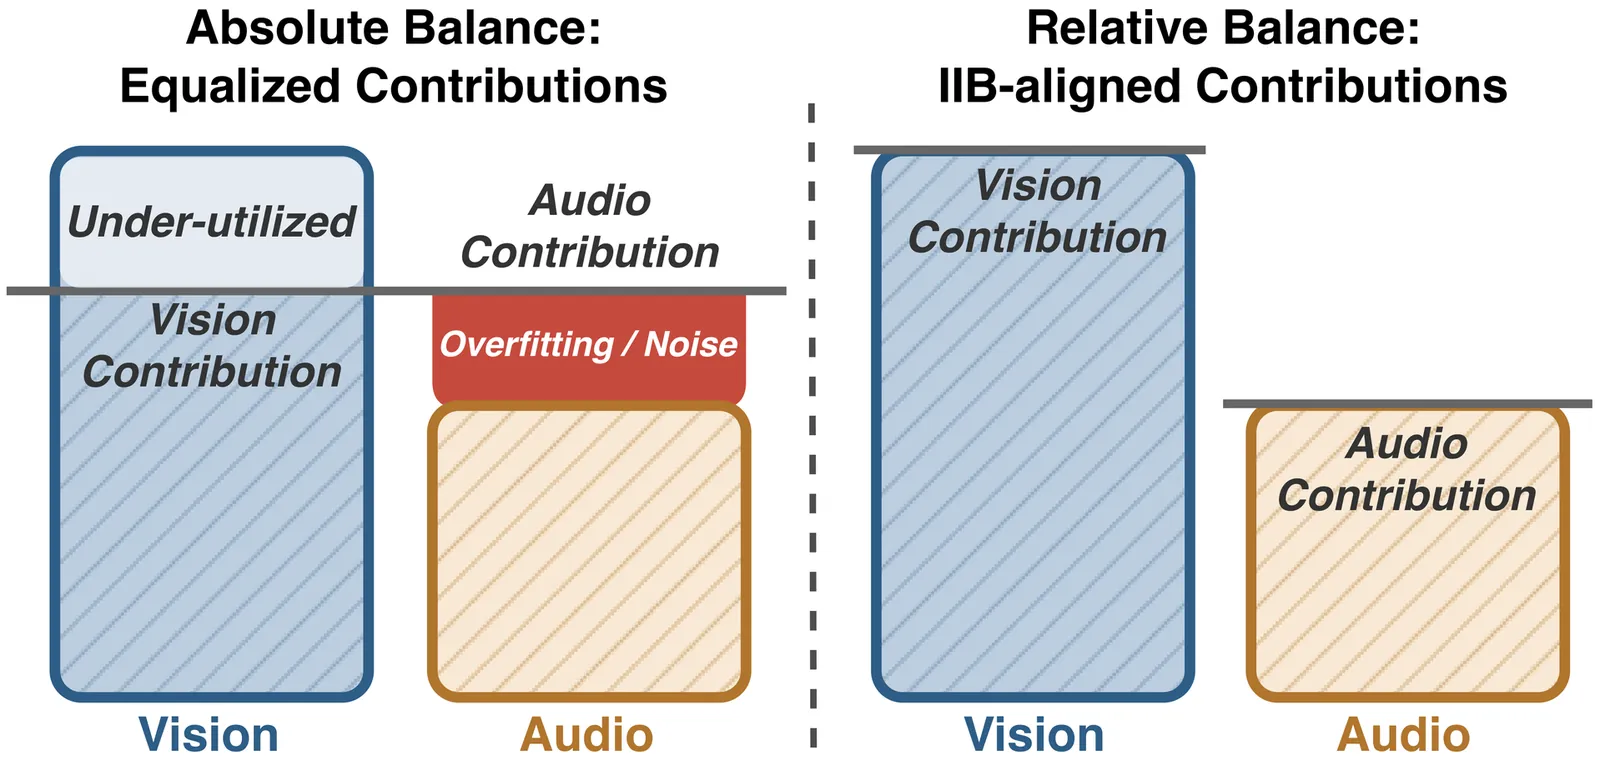
Beyond Forced Modality Balance: Intrinsic Information Budgets for Multimodal Learning
Multimodal models often converge to a dominant-modality solution, in which a stronger, faster-converging modality overshadows weaker ones. This modality imbalance causes suboptimal performance. Existing methods attempt to balance different modalities by reweighting gradients or losses. However, they overlook the fact that each modality has finite information capacity. In this work, we propose IIBalance, a multimodal learning framework that aligns the modality contributions with Intrinsic Information Budgets (IIB). We propose a task-grounded estimator of each modality's IIB, transforming its capacity into a global prior over modality contributions. Anchored by the highest-budget modality, we design a prototype-based relative alignment mechanism that corrects semantic drift only when weaker modalities deviate from their budgeted potential, rather than forcing imitation. During inference, we propose a probabilistic gating module that integrates the global budgets with sample-level uncertainty to generate calibrated fusion weights. Experiments on three representative benchmarks demonstrate that IIBalance consistently outperforms state-of-the-art balancing methods and achieves better utilization of complementary modality cues. Our code is available at: https://github.com/XiongZechang/IIBalance.
2603.17347Mar 2026
View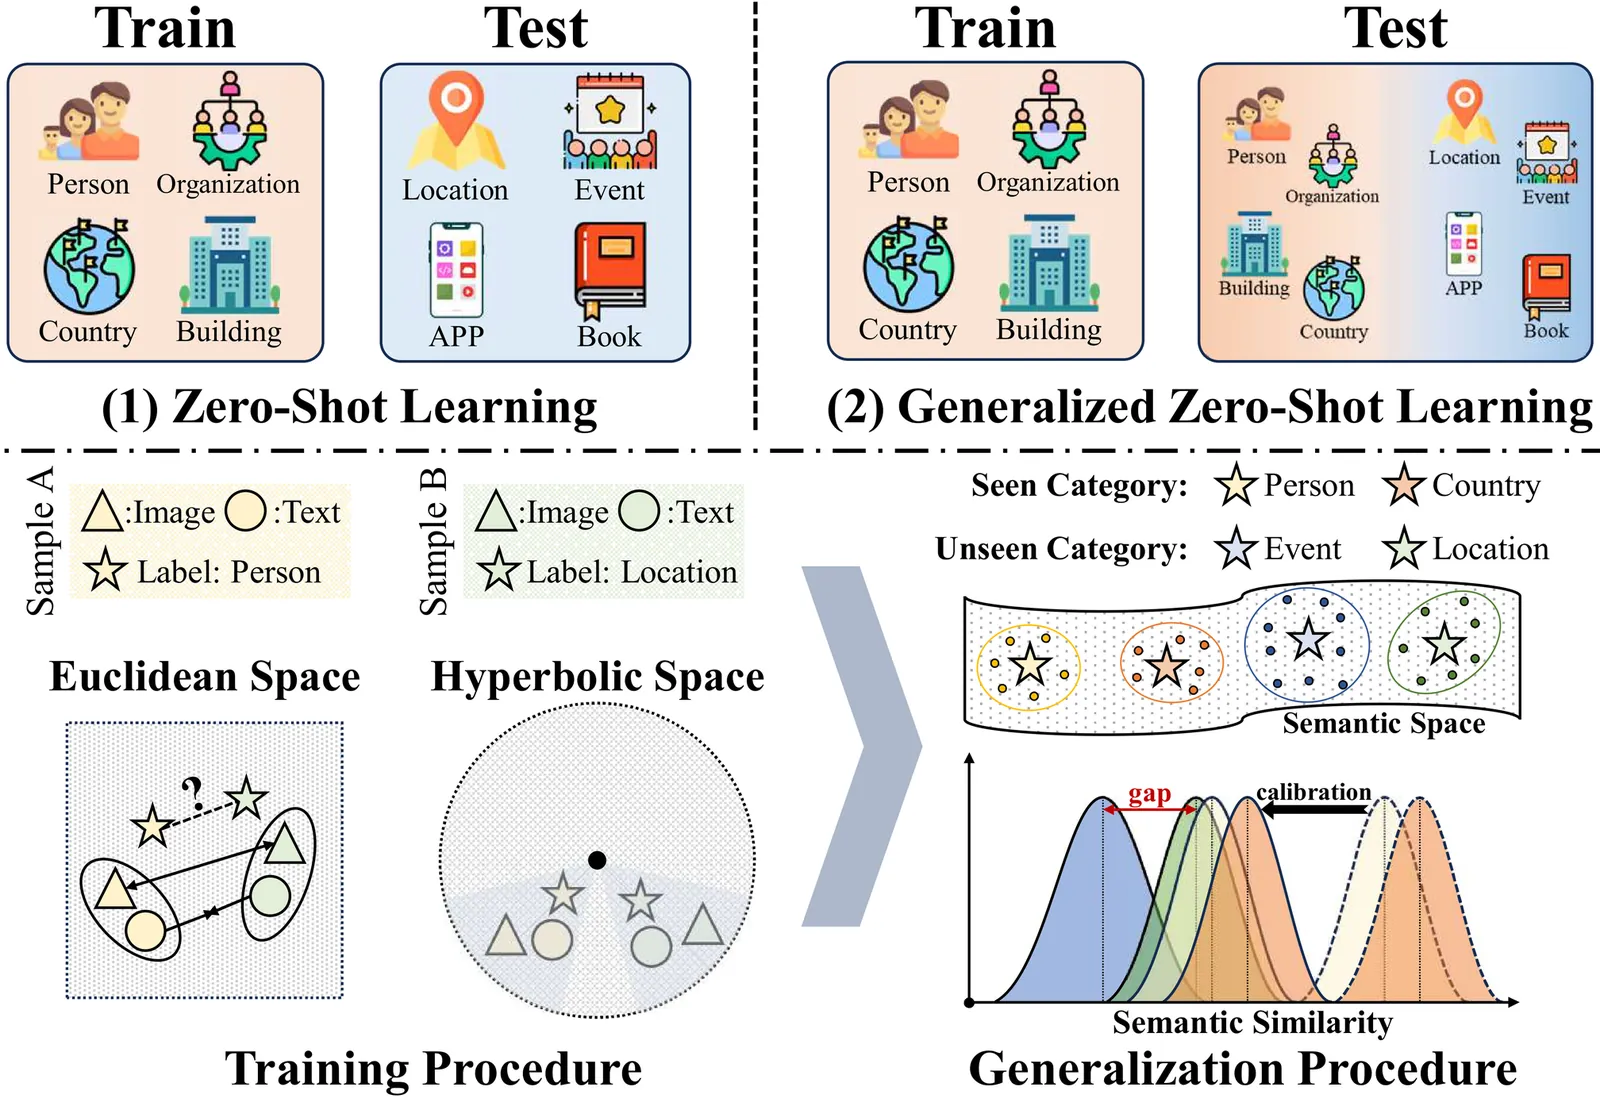
Hyperbolic Multimodal Generative Representation Learning for Generalized Zero-Shot Multimodal Information Extraction
Multimodal information extraction (MIE) constitutes a set of essential tasks aimed at extracting structural information from Web texts with integrating images, to facilitate the structural construction of Web-based semantic knowledge. To address the expanding category set including newly emerging entity types or relations on websites, prior research proposed the zero-shot MIE (ZS-MIE) task which aims to extract unseen structural knowledge with textual and visual modalities. However, the ZS-MIE models are limited to recognizing the samples that fall within the unseen category set, and they struggle to deal with real-world scenarios that encompass both seen and unseen categories. The shortcomings of existing methods can be ascribed to two main aspects. On one hand, these methods construct representations of samples and categories within Euclidean space, failing to capture the hierarchical semantic relationships between the two modalities within a sample and their corresponding category prototypes. On the other hand, there is a notable gap in the distribution of semantic similarity between seen and unseen category sets, which impacts the generative capability of the ZS-MIE models. To overcome the disadvantages, we delve into the generalized zero-shot MIE (GZS-MIE) task and propose the hyperbolic multimodal generative representation learning framework (HMGRL). The variational information bottleneck and autoencoder networks are reconstructed with hyperbolic space for modeling the multi-level hierarchical semantic correlations among samples and prototypes. Furthermore, the proposed model is trained with the unseen samples generated by the decoder, and we introduce the semantic similarity distribution alignment loss to enhance the model's generalization performance. Experimental evaluations on two benchmark datasets underscore the superiority of HMGRL compared to existing baseline methods.
2603.16259Mar 2026
View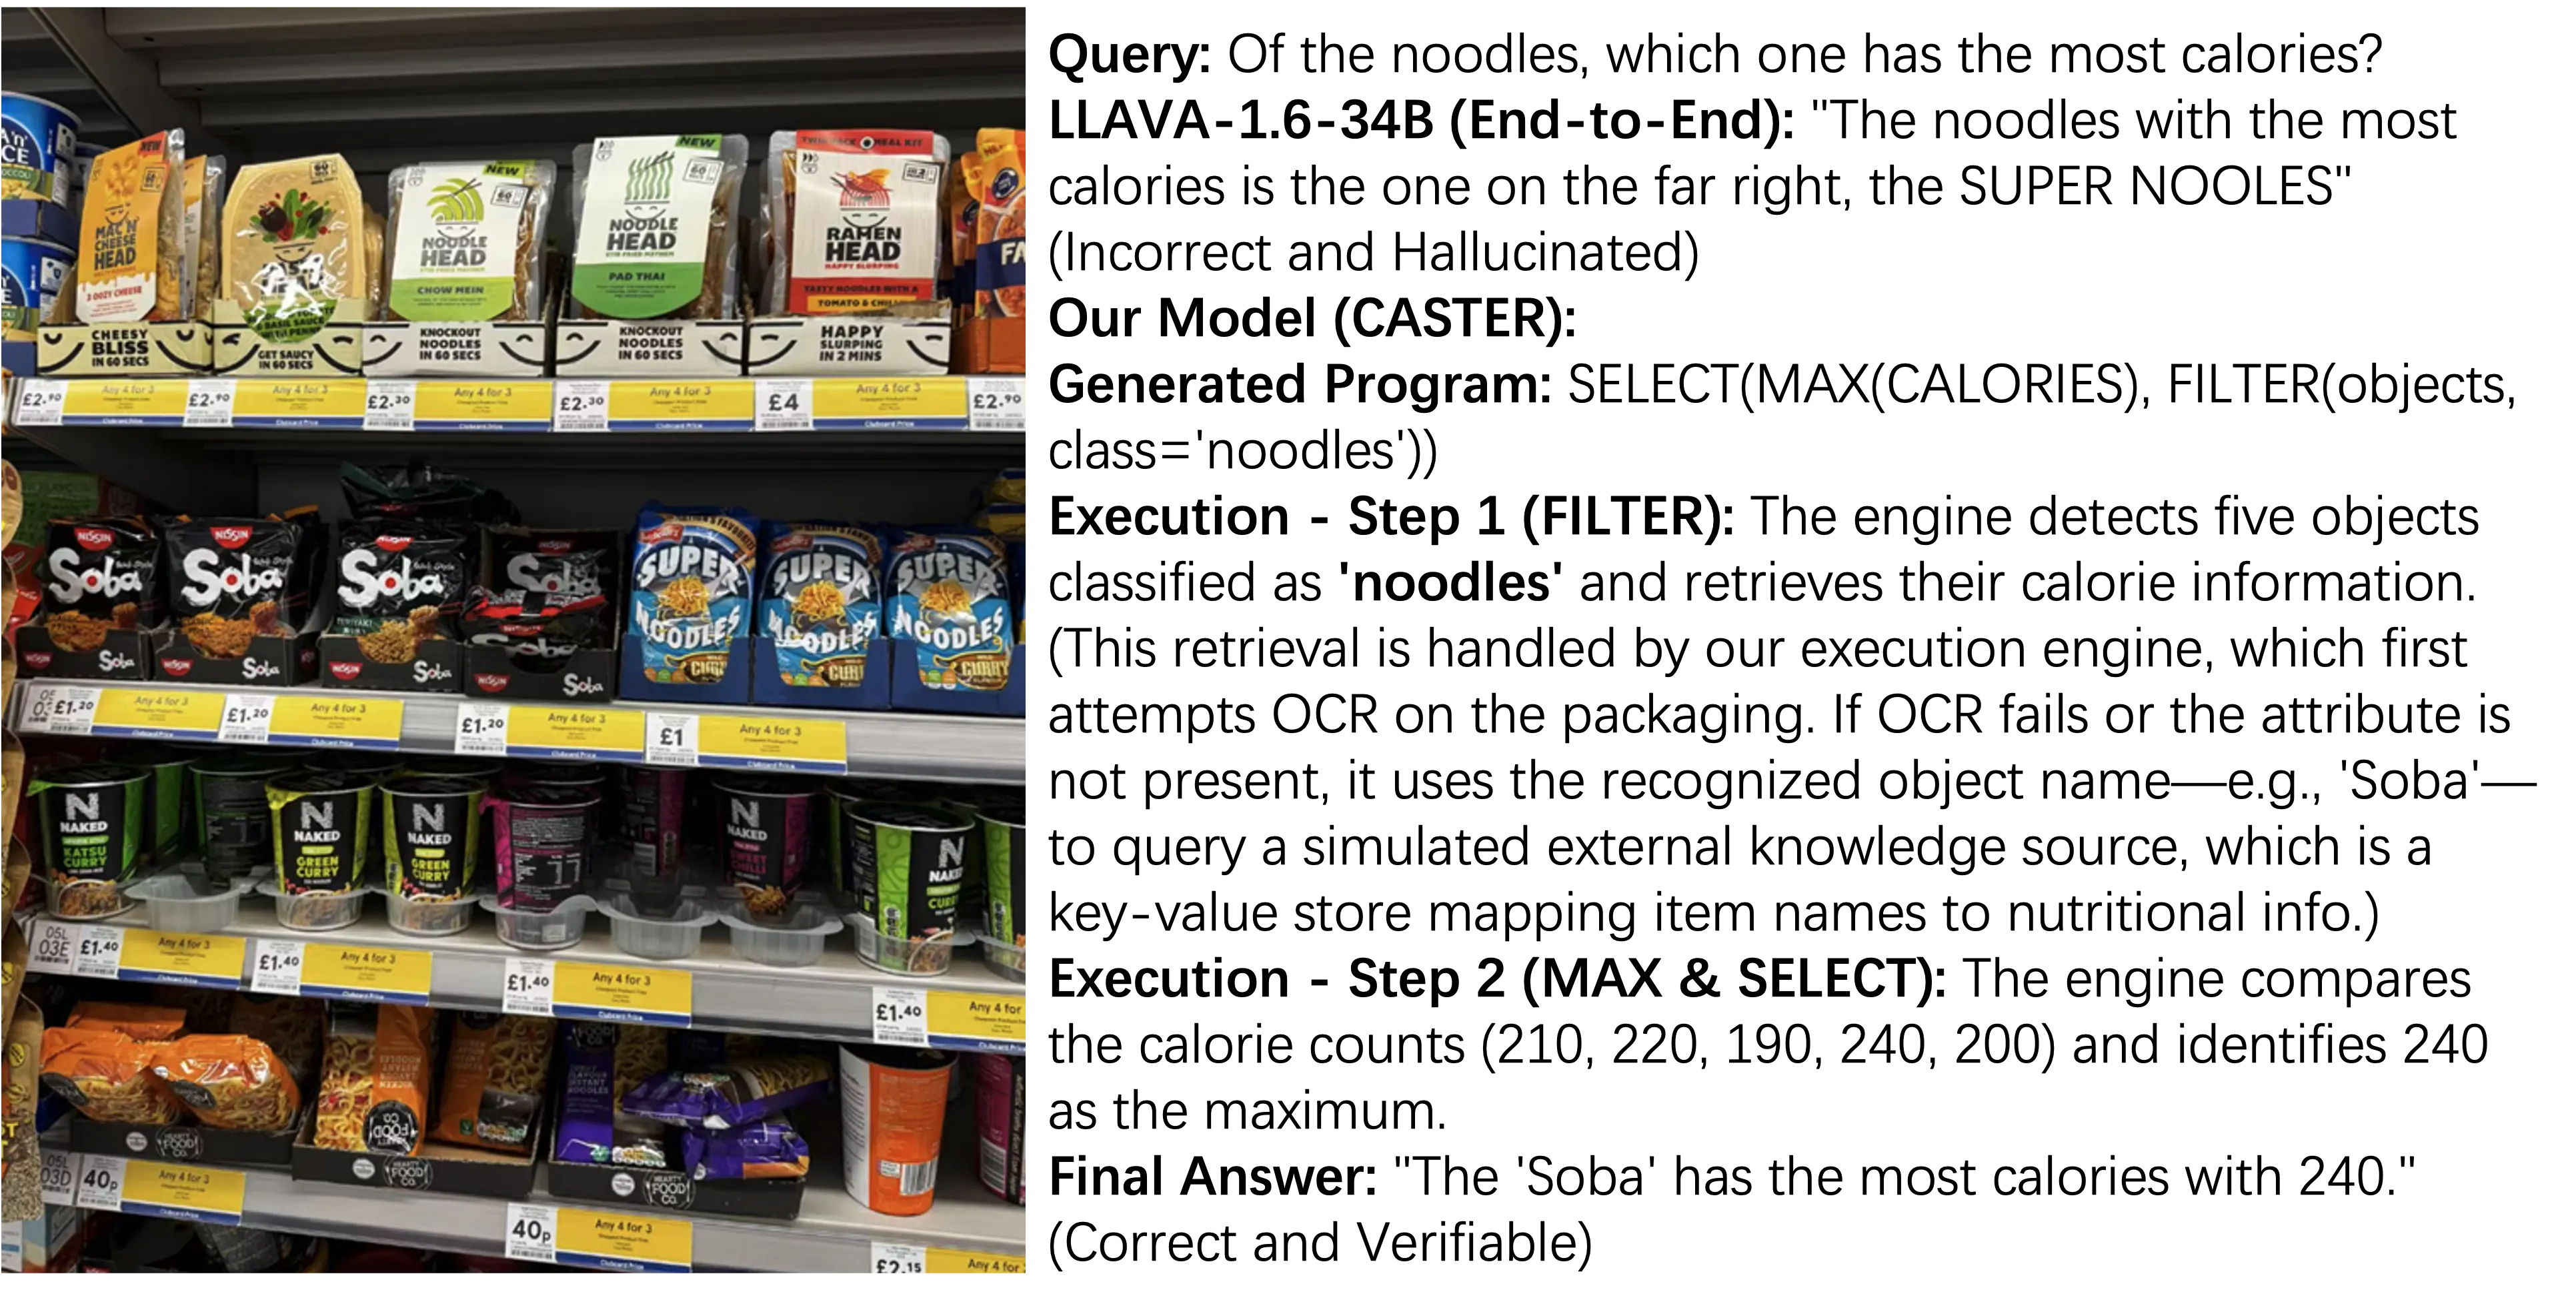
Visual Set Program Synthesizer
A user pointing their phone at a supermarket shelf and asking "Which soda has the least sugar?" poses a difficult challenge for current visual Al assistants. Such queries require not only object recognition, but explicit set-based reasoning such as filtering, comparison, and aggregation. Standard endto-end MLLMs often fail at these tasks because they lack an explicit mechanism for compositional logic. We propose treating visual reasoning as Visual Program Synthesis, where the model first generates a symbolic program that is executed by a separate engine grounded in visual scenes. We also introduce Set-VQA, a new benchmark designed specifically for evaluating set-based visual reasoning. Experiments show that our approach significantly outperforms state-of-the-art baselines on complex reasoning tasks, producing more systematic and transparent behavior while substantially improving answer accuracy. These results demonstrate that program-driven reasoning provides a principled alternative to black-box visual-language inference.
2603.15997Mar 2026
ViewPage 1 of 31